
In 2023 the air at Khumaltar in Lalitpur held, on average, about 46 micrograms of fine dust (PM2.5) in every cubic meter. But no one breathed “the average”. In April the month’s average was 80; in July it was 14. One month’s air was nearly six times as dusty as another’s.
An average tells you where the middle of the data is. It doesn’t tell you how far the values swing around it, and for air, rain, prices or marks the swing matters as much as the middle. This unit measures it: quartiles and percentiles cut ordered data into equal parts, the quartile deviation, mean deviation and standard deviation put one number on the spread, and a box plot draws it. In Back to the air you will describe Lalitpur’s year with all of them.
5.1 Quartiles and percentiles
Statistics is the branch of mathematics that collects data, presents it, sorts it and analyses it. It is very old: the rulers of Egypt, Babylon and Rome kept simple records of their people, trade and taxes. Modern statistics grew in Europe from the 1600s on, with the scientific way of measuring and testing; from 1700 on mathematicians such as Jacob Bernoulli, Thomas Bayes and Pierre-Simon Laplace worked out the mathematics of chance and error that it rests on. Today statistics is used in the natural and social sciences, in medicine, business and government, and on your phone.
Using numbers to describe a set of data (its middle, its spread, its shape) is called descriptive statistics, and showing the data in tables and pictures so that a pattern can be seen is part of it. That is this unit.
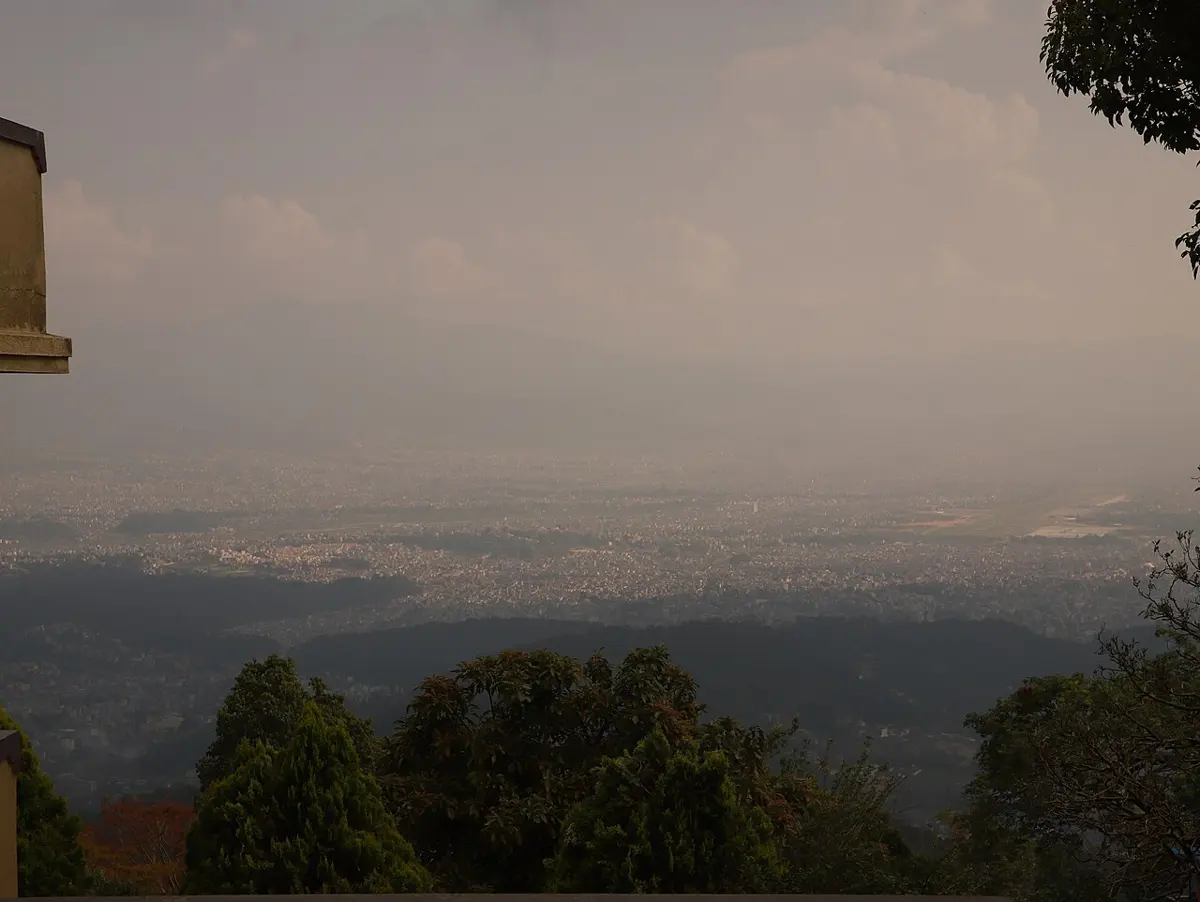
To describe how the months spread out, we first put them in order and cut the ordered list into equal parts. That is what quartiles and percentiles do.
5.1.1 Quartiles of individual and discrete data
Data comes in two forms in this unit.
- An individual series lists every value on its own: the weights of 11 students, 35 kg, 39 kg, 52 kg, …
- A discrete series gives each value with its frequency, how many times it occurs: 5 teachers aged 25, 8 aged 30, 10 aged 35, … in a table.
Here is a smaller set to try it on. The temperature in Kathmandu was read every 2 hours on a winter day:
5 °C, 7 °C, 3 °C, 10 °C, 12 °C, 15 °C, 9 °C, 17 °C, 13 °C, 19 °C, 8 °C
In ascending order they are
3 °C, 5 °C, 7 °C, 8 °C, 9 °C, 10 °C, 12 °C, 13 °C, 15 °C, 17 °C, 19 °C
There are 11 readings, and the 6th, 10 °C, stands in the middle with 5 readings on each side: it is the median, and it cuts the data into two equal halves. To cut the data into four equal parts we need three cutting points, just as a rope needs three cuts to make four pieces.
Counting from the left, the 3rd reading, 7 °C, the 6th, 10 °C, and the 9th, 15 °C, divide the readings into four equal parts. The values that divide ordered data into four equal parts are called quartiles:
- the first quartile or lower quartile, Q₁ (here 7 °C): about 25% of the data lies below it and 75% above;
- the second quartile, Q₂, which is the median, (here 10 °C): 50% below, 50% above;
- the third quartile or upper quartile, Q₃ (here 15 °C): about 75% below, 25% above.
Thirty-nine students’ heights are arranged in ascending order. About how many of them are shorter than the third quartile?
Pick an answer to see why.
5.1.2 Quartiles of an individual series
With 11 values the quartiles were the 3rd, 6th and 9th. Where are they for any number of values? If an individual series has N values, in ascending order,
For the 11 temperatures, : the 3rd, 6th and 9th, as we found by counting.
If is not a whole number, the quartile lies between two items. A place like 2.25 means “the 2nd item, plus a quarter of the way to the 3rd”:
Worked examples
5.1.3 Quartiles of a discrete series
In a discrete series the values repeat, so we can’t just count along a list, but the places are found the same way. With , the sum of the frequencies,
To find which value stands at a place, make a cumulative frequency (cf) column: the running total of the frequencies. A value’s cf says how many items there are up to and including it. The item at a place is the value whose cf is equal to the place or just greater than it.
In a discrete series the cumulative frequencies are 4, 12, 17, 20, 23, 28 for the values 45, 47, 49, 51, 53, 55. Which value is the 12th item?
Pick an answer to see why.
5.1.4 Percentiles
The 99 values that divide ordered data into 100 equal parts are called percentiles, written . About n% of the data lies below . Like the quartiles, the place of the nth percentile, in an individual or a discrete series, is
Here are the heights (cm) of 19 students:
150, 140, 132, 125, 133, 126, 123, 137, 145, 122, 149, 147, 142, 148, 136, 124, 128, 141, 144
In ascending order:
122, 123, 124, 125, 126, 128, 132, 133, 136, 137, 140, 141, 142, 144, 145, 147, 148, 149, 150
They must be in ascending order, because the percentiles grow as n grows: must be at least as big as P₅. Then, with N + 1 = 20,
- item = 122 cm
- item = 141 cm
- item, between the 16th (147) and the 17th (148): cm
- item = 150 cm
Notice that , and : quartiles are just three of the percentiles.
Exercise 5.1
Question 1
What are individual and discrete series? Explain with examples.
Answer
What is meant by a quartile? Explain with an example.
Answer
What is meant by a percentile? How are percentiles denoted?
Answer
Write the formulas for Q₁, Q₂ and Q₃ of an individual series.
Answer
Questions 2 to 5
What is the conclusion of Activity 1 (dividing your class’s marks into four equal parts)?
Answer
What is the conclusion of Activity 2 (cutting a rope)?
Answer
Write the formulas for Q₁, Q₂ and Q₃ of a discrete series.
Answer
Make up one example of an individual series and one of a discrete series from daily life, different from those in this unit.
Answer
Question 6
Explain the graph in Figure 5.8.
Answer
Question 7
In Figure 5.9, what does “80% below you” mean?
Answer
Question 8
Sabita finds the three quartiles of each set of data below and says that the second quartile is the median. Find the quartiles too. Do you agree with her? Give reasons.
25, 48, 32, 52, 21, 64, 29, 57
Answer
19, 20, 21, 23, 23, 24, 25, 27, 31
Answer
Questions 9 to 12
In a survey of 543 people who watch television, their ages were:
| Age (years) | 20 | 30 | 40 | 50 | 60 | 70 | 80 |
|---|---|---|---|---|---|---|---|
| Number of people | 3 | 61 | 132 | 153 | 140 | 51 | 3 |
Find the first and third quartiles.
Answer
A village survey found how much rice each household sold last year:
| Rice sold (pathi) | 5 | 15 | 25 | 35 | 45 | 55 |
|---|---|---|---|---|---|---|
| Number of households | 3 | 7 | 15 | 5 | 8 | 2 |
a. Find the first quartile. b. Find the third quartile. c. Show that the second quartile is the median.
Answer
The marks of 19 students in a mathematics test were:
30, 21, 54, 30, 37, 45, 25, 47, 37, 24, 42, 45, 33, 28, 52, 50, 47, 20, 35
a. Find the 40th percentile. b. Find the 80th percentile. c. Show that the 50th percentile equals the second quartile.
Answer
The marks of students in a mathematics annual examination:
| Marks | 10 | 20 | 30 | 40 | 50 | 60 |
|---|---|---|---|---|---|---|
| Number of students | 3 | 7 | 15 | 5 | 8 | 2 |
a. Find the 30th percentile. b. Find the 85th percentile. c. Show that the 50th percentile equals the second quartile.
Answer
Questions 13 and 14
Make up a question with a real setting based on a discrete series. Then a. find the first quartile, b. find the third quartile, c. show that the second quartile is the median.
Answer
Make up a question with a real setting based on an individual series. Then a. find the 20th percentile, b. find the 60th percentile, c. show that the 50th percentile equals the second quartile.
Answer
5.2 Dispersion of individual and discrete series
Here are the prices of edible oil (Rs per liter) and of a 25 kg sack of rice (Rs per sack) in a Nepali market over the last 11 months:
| Month | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 |
|---|---|---|---|---|---|---|---|---|---|---|---|
| Oil (Rs/liter) | 180 | 200 | 230 | 240 | 245 | 250 | 260 | 270 | 300 | 310 | 315 |
| Rice (Rs/sack) | 1,600 | 1,700 | 1,850 | 2,040 | 2,145 | 2,250 | 2,260 | 2,300 | 2,350 | 2,400 | 2,450 |
How much the values of a set of data are scattered or spread out from their middle is called dispersion. A measure of dispersion is a single number that says how spread out the data are: small for data bunched together, large for data spread wide. The range, the largest value minus the smallest, is the simplest, but it hangs on just two values, which may be unusual. The measures in this unit use more of the data.
Each measure comes in two forms. An absolute measure (the quartile deviation, mean deviation or standard deviation itself) is in the data’s own units: rupees, kilograms, °C. A relative measure, a coefficient, divides it by an average and has no units, so it can compare sets in different units or of very different sizes, such as rupees for a liter of oil and rupees for a sack of rice.
5.2.1 Quartile deviation and its coefficient
Measure the heights of all the people of a country and you will find huge differences, from toddlers to the tallest adults. Measure the heights of the players of its national football team and the differences are much smaller. The quartile deviation is one way of saying how much smaller.
At a village meeting the ages (years) of the people gathered were:
40, 46, 35, 50, 38, 57, 44, 52, 60, 48, 55, 56, 67, 70, 62
In ascending order: 35, 38, 40, 44, 46, 48, 50, 52, 55, 56, 57, 60, 62, 67, 70. With N = 15, :
- Q₁ = the 4th item = 44 years
- Q₂ = the 8th item = 52 years
- Q₃ = the 12th item = 60 years
The middle half of the people, those between the lower and the upper quartile, are aged 44 to 60. The width of that middle half is the interquartile range:
Half of it is the quartile deviation (Q.D.), also called the semi-interquartile range:
and the relative measure based on it is the coefficient of quartile deviation:
For the village ages:
What it means: the middle half of the meeting spans 16 years of age. Half of that, 8 years, is how far, roughly, a typical person in that middle half is from the middle of the group.
The coefficient is a ratio: dividing by Q₃ + Q₁, which is twice the middle of the two quartiles, compares the spread with the size of the values. For the 11 months of prices, Q₁ and Q₃ are the 3rd and 9th prices:
- oil: Rs 35, coefficient ;
- rice: Rs 250, coefficient .
Rice’s quartile deviation is seven times oil’s, but a sack of rice costs about eight times a liter of oil. The coefficients say that, for their size, the two prices swung about equally, oil a little more.
The heights of two groups of students have the same quartile deviation, 6 cm. Group P has Q₁ = 120 cm and Group Q has Q₁ = 150 cm. Which group is more homogeneous, relative to its size?
Pick an answer to see why.
Worked examples
Exercise 5.2
Questions 1 to 3
What is dispersion? Explain with an example.
Answer
What is meant by quartile deviation? Which quartiles are used to find it? Give reasons.
Answer
What is meant by the interquartile range?
Answer
Question 4
In Figure 5.10, the first quartile is Q₁ = 24 and the third quartile Q₃ = 38. Find the quartile deviation and the coefficient of quartile deviation.
Answer
Questions 5 to 7
The lower and upper quartiles of a set of individual data are 30 and 40. a. Find the quartile deviation. b. Find the coefficient of quartile deviation.
Answer
The first quartile of a set of data is Q₁ = 35 and the quartile deviation is 20. a. Find the third quartile. b. Find the coefficient of quartile deviation.
Answer
- a.The quartile deviation of a set of discrete data is 14 and its coefficient is . Find the first quartile.
- b.The coefficient of quartile deviation of a set of individual data is and its third quartile is 15. Find the first quartile and the quartile deviation.
- c.The first quartile of a set of individual data is 12 and its quartile deviation is 2. Find the third quartile and the coefficient of quartile deviation.
Answer
Question 8
Find the quartile deviation and its coefficient of each set of data.
Price (Rs): 150, 200, 250, 400, 160, 210, 420
Answer
Temperature (°C): 13, 40, 27, 30, 25, 22, 21, 18, 12, 13, 10
Answer
Body weight (kg): 20, 18, 25, 12, 9, 6, 21, 42, 35, 28
Answer
Students’ lunch spending (Rs): 50, 80, 85, 75, 70, 90, 100, 105, 120, 110, 130
Answer
Questions 9 to 13
The weights of 28 students of Class 9 of a school in the first week of Poush:
| Weight (kg) | 45 | 47 | 49 | 51 | 53 | 55 |
|---|---|---|---|---|---|---|
| Number of students | 4 | 8 | 5 | 3 | 3 | 5 |
Find the quartile deviation and its coefficient.
Answer
Temperatures measured at the same time in towns in different places:
| Temperature (°C) | 10 | 15 | 20 | 25 | 30 |
|---|---|---|---|---|---|
| Number of towns | 3 | 7 | 10 | 8 | 2 |
Find the quartile deviation and its coefficient.
Answer
The marks of 39 students of Class 9 of a community school in the second terminal examination:
| Marks | 40 | 45 | 50 | 55 | 60 | 64 | 68 |
|---|---|---|---|---|---|---|---|
| Number of students | 5 | 7 | 8 | 6 | 4 | 6 | 3 |
Find the quartile deviation and its coefficient.
Answer
A school measures its students’ heights every term:
| Height (cm) | 153 | 155 | 157 | 159 | 161 | 163 | 165 | 167 | 169 |
|---|---|---|---|---|---|---|---|---|---|
| Number of students | 8 | 2 | 4 | 6 | 3 | 4 | 7 | 1 | 4 |
Find the quartile deviation and its coefficient.
Answer
A survey of people of different ages who like to watch Nepali films:
| Age (years) | 20 | 30 | 40 | 50 | 60 | 70 | 80 |
|---|---|---|---|---|---|---|---|
| Number of people | 3 | 61 | 132 | 153 | 140 | 51 | 3 |
Find the interquartile range and the coefficient of quartile deviation.
Answer
Questions 14 and 15
Make up a question with a real setting based on individual data, collect the data, and a. find the first quartile, b. find the third quartile, c. find the quartile deviation and its coefficient.
Answer
Make up a question with a real setting based on discrete data, collect the data, and a. find the first quartile, b. find the third quartile, c. find the quartile deviation and its coefficient. d. Why don’t we need the second quartile to find the interquartile range and its coefficient?
Answer
5.3 Mean deviation and its coefficient
The quartile deviation looks only at the two quartiles. The mean deviation uses every value: it asks how far, on average, the values are from their middle. That is often what people really want to know. A factory filling 1 kg bags of flour wants every bag close to 1 kg, and asks how far, on average, the bags are off. A weather forecast can be judged the same way, by the average size of its misses (a forecast that is 2 °C too warm one day and 2 °C too cold the next is off by 2 °C on average, not by 0).
Two friends, Pemba and Tashi, took ten mathematics tests of 25 marks each during a year:
Pemba: 17, 19, 20, 16, 22, 23, 21, 20.5, 18, 15
Tashi: 9, 10, 3, 15, 20, 16, 5, 25, 21, 23
The average of the absolute values of the differences between each item and a measure of central tendency (the mean or the median) is called the mean deviation (M.D.), or average deviation. The absolute value |X − X| is the distance, without its sign: |3 − 9| = | − 6| = 6. Without it the minus and plus differences would cancel: the differences from the mean always add up to 0.
5.3.1 Mean deviation of an individual series
Take the eight values 3, 6, 6, 7, 8, 11, 16, 15.
First find the mean: .
Then find each value’s distance from 9:
| X | 3 | 6 | 6 | 7 | 8 | 11 | 15 | 16 |
|---|---|---|---|---|---|---|---|---|
| 6 | 3 | 3 | 2 | 1 | 2 | 6 | 7 |
Last, average the distances: .
What it means: on average the values are 3.75 away from their mean, 9.
In general, for an individual series of N values:
a. Mean deviation from the mean
b. Mean deviation from the median
D is always positive or 0. For the eight values, the median is the 4.5th item, , the distances from it are 4.5, 1.5, 1.5, 0.5, 0.5, 3.5, 7.5, 8.5, and the mean deviation from the median is .
The mean deviation is an absolute measure, in the data’s units. To compare sets in different units, or of different sizes, we use its coefficient:
For Pemba, M.D. ≈ 2.15 and the coefficient ; for Tashi, M.D. ≈ 6.36 and . Tashi’s marks swing about four times as much as Pemba’s, for their size.
The distances of five values from their mean are 4, 1, 0, 2 and 3. What is their mean deviation?
Pick an answer to see why.
5.3.2 Mean deviation of a discrete series
In a discrete series each value X comes f times, so each distance counts f times. With :
a. From the mean
b. From the median
The coefficients are and , as before.
Worked examples
Exercise 5.3
Questions 1 to 7
What is meant by mean deviation?
Answer
How is the mean deviation found?
Answer
Where is the mean deviation used in daily life?
Answer
Why is the mean deviation thought more reliable than the quartile deviation?
Answer
Why is it not enough to find the mean deviation? Why is its coefficient found too?
Answer
Explain how the mean deviation is found from the mean.
Answer
Explain how the mean deviation is found from the median.
Answer
Question 8
Find the mean deviation from the mean and its coefficient.
Price (Rs): 150, 200, 250, 400, 160, 210, 422
Answer
Temperature (°C): 20, 18, 25, 12, 9, 6, 22, 45, 35, 28
Answer
Body weight (kg): 13, 40, 27, 30, 25, 22, 21, 18, 12, 13, 10
Answer
Students’ lunch spending (Rs): 50, 80, 85, 75, 70, 90, 100, 105, 120, 110, 127
Answer
Rainfall (mm): 14, 10, 8, 12, 22, 28, 16, 24, 26
Answer
Scores: 17, 10, 15, 7, 13, 9, 6, 18, 11, 14
Answer
Question 9
Find the mean deviation from the median and its coefficient of the same data.
Price (Rs): 150, 200, 250, 400, 160, 210, 422
Answer
Temperature (°C): 20, 18, 25, 12, 9, 6, 22, 45, 35, 28
Answer
Body weight (kg): 13, 40, 27, 30, 25, 22, 21, 18, 12, 13, 10
Answer
Students’ lunch spending (Rs): 50, 80, 85, 75, 70, 90, 100, 105, 120, 110, 127
Answer
Rainfall (mm): 14, 10, 8, 12, 22, 28, 16, 24, 26
Answer
Scores: 17, 10, 15, 7, 13, 9, 6, 18, 11, 14
Answer
Questions 10 to 13
The first 10 natural numbers: 1, 2, 3, 4, 5, 6, 7, 8, 9, 10.
- a.Find the mean deviation from the mean and its coefficient.
- b.Find the mean deviation from the median and its coefficient.
- c.Is there any difference between the two mean deviations? Give reasons.
Answer
The marks of the students of Class 9 of a school in Science and Technology in the second terminal examination:
| Marks | 40 | 45 | 50 | 55 | 60 | 64 | 68 |
|---|---|---|---|---|---|---|---|
| Number of students | 5 | 7 | 8 | 6 | 4 | 6 | 3 |
a. In which kind of series are the data given? b. How many students are there? c. Find the mean deviation from the mean and its coefficient. d. Find the mean deviation from the median and its coefficient.
Answer
The temperatures recorded at a place during a day:
| Temperature (°C) | 20 | 25 | 28 | 29 | 33 | 38 | 42 | 43 |
|---|---|---|---|---|---|---|---|---|
| Frequency | 6 | 20 | 24 | 28 | 15 | 4 | 2 | 1 |
a. In which kind of series are the data given? b. Find . c. Find the mean deviation from the mean and its coefficient. d. Find the mean deviation from the median and its coefficient.
Answer
The daily rainfall at a place during five months (Jestha to Ashoj):
| Rain (mm) | 20 | 25 | 30 | 35 | 40 |
|---|---|---|---|---|---|
| Number of days | 5 | 8 | 12 | 10 | 5 |
a. Write the formula for the median of discrete data. b. Find the mean. c. Find the median. d. Find the mean deviation from the mean and its coefficient. e. Find the mean deviation from the median and its coefficient.
Answer
5.4 Standard deviation and its coefficient
The mean deviation throws away the signs of the deviations to stop them canceling. There is another way to get rid of a minus sign: square it, since is positive like . Square each deviation from the mean, average the squares, and take the square root to get back to the data’s units. The result is the standard deviation, the most used measure of dispersion of all.
The standard deviation (S.D.) is the square root of the mean of the squares of the deviations of the items from their mean. It is written , the small Greek letter sigma:
The square of the standard deviation, the mean of the squared deviations, is the variance, . The smaller the standard deviation, the more uniform the data, and the better the mean represents them.
Why is the standard deviation used more than the others? It uses every value, like the mean deviation, but squares are easy to work with in algebra (absolute values are not), so it leads on to most of the rest of statistics: the shape of the bell curve, the margins of error of surveys and the “±” after a measurement are all given in standard deviations.
5.4.1 Standard deviation of an individual series
There are three ways to work it out; all give the same answer.
a. Actual mean method. Find the mean ; find each deviation d = X − X; square each and add, ; then
This is easiest when the mean is a whole number; with a decimal mean the squares get long.
b. Direct method. No mean is subtracted: add the values, , and their squares, ; then
In words: the mean of the squares minus the square of the mean.
c. Assumed mean method. Take a convenient value near the middle as the assumed mean A; find d = X − A for each value, then and :
If A happens to be the actual mean, and this is method a.
5.4.2 Standard deviation of a discrete series
With frequencies, each value’s square counts f times, and .
a. Actual mean method.
b. Direct method.
c. Assumed mean method. Choose A; find d = X − A, then fd and :
5.4.3 Coefficient of standard deviation
The standard deviation is an absolute measure, in the data’s units. The relative measure based on it is the coefficient of standard deviation:
The smaller it is, the more uniform the data. When comparing sets, the one with the smaller coefficient is the more uniform (more consistent).
5.4.4 Coefficient of variation
The coefficient of standard deviation is often a small decimal, so it is usually multiplied by 100 and written as a percentage. That percentage is the coefficient of variation (C.V.):
A large C.V. means more dispersion; a small one more uniformity. For Pemba and Tashi, and 7.28, and C.V. and 49.5%: Pemba’s marks are far more consistent.
Two sets of data have means 50 and 200 and the same standard deviation, 10. Which statement is true?
Pick an answer to see why.
Worked examples
Exercise 5.4
Question 1
What is meant by standard deviation?
Answer
Name the methods by which the standard deviation can be found.
Answer
Write the formulas for the standard deviation of individual and discrete data by each method.
Answer
Explain clearly how the standard deviation is found.
Answer
Where is the standard deviation used in daily life?
Answer
What is meant by the coefficient of standard deviation?
Answer
Question 2
Define the coefficient of variation and explain how it is found.
Answer
How does a higher or lower coefficient of variation help in analyzing data?
Answer
Question 3
Find the standard deviation, its coefficient and the coefficient of variation.
Price (Rs): 150, 200, 250, 400, 160, 210, 420
Answer
Temperature (°C): 20, 18, 25, 12, 9, 6, 21, 42, 35, 28
Answer
Body weight (kg): 13, 40, 27, 30, 25, 22, 21, 18, 12, 13, 10
Answer
Students’ snack spending (Rs): 50, 80, 85, 75, 70, 90, 100, 105, 120, 110, 130
Answer
Rainfall (mm): 14, 10, 8, 12, 22, 28, 16, 24, 26
Answer
Marks: 17, 10, 15, 7, 13, 9, 6, 18, 11, 14
Answer
Questions 4 and 5
The daily wages of a supermarket’s employees:
| Wage (Rs) | 1,200 | 1,300 | 1,400 | 1,500 | 1,600 |
|---|---|---|---|---|---|
| Number of employees | 8 | 12 | 15 | 9 | 6 |
a. Find the average wage. b. Find the standard deviation. c. Find the coefficient of variation.
Answer
Find the standard deviation, its coefficient and the coefficient of variation.
a.
| Age (years) | 10 | 12 | 13 | 14 | 15 | 16 |
|---|---|---|---|---|---|---|
| Number of children | 8 | 12 | 15 | 9 | 6 | 5 |
b.
| Marks | 35 | 45 | 50 | 55 | 60 | 65 | 70 | 75 |
|---|---|---|---|---|---|---|---|---|
| Number of students | 8 | 4 | 5 | 5 | 6 | 6 | 6 | 1 |
c.
| Wage (Rs) | 1,000 | 1,050 | 1,100 | 1,150 | 1,200 |
|---|---|---|---|---|---|
| Employees | 14 | 9 | 5 | 8 | 5 |
Answer
5.5 Box and whisker plot
A number like sums up spread in one value. A box and whisker plot (or box plot) shows it at a glance, and it is the easiest way to compare two or more sets of data side by side. It is drawn from five numbers, the five-number summary:
- the smallest value,
- the lower quartile Q₁,
- the median ,
- the upper quartile Q₃,
- the largest value.
On a scale, a box is drawn from Q₁ to Q₃ with a line across it at the median, and a whisker (a line) from each end of the box out to the smallest and to the largest value. The five numbers cut the data into four parts with about 25% of the data in each: the left whisker, the two halves of the box, and the right whisker.
To draw a box plot:
- Find the five-number summary: arrange the data in ascending order, find the smallest and largest values, Q₁, the median and Q₃.
- Draw a scale that covers the smallest and largest values, and mark the five numbers on it with short upright lines.
- Join the lines at Q₁ and Q₃ into a box, with the median’s line inside it, and draw the whiskers from the box out to the smallest and the largest values.
A box plot’s box runs from 40 to 70. About what percentage of the data lies between 40 and 70?
Pick an answer to see why.
Exercise 5.5
Questions 1 and 2
What is the five-number summary of a box plot? Write the five-number summary of the box plot below.
Answer
The box plot shows the heights (inches) of the students in a secondary school basketball team. Write its five-number summary.
Answer
Question 3
The box plot shows the weights (kg) of the students of a secondary school.
What is the greatest weight?
Answer
What is the least weight?
Answer
What is the median weight?
Answer
What percentage of the students weigh more than 72 kg?
Answer
What percentage of the students weigh between 88 kg and 96 kg?
Answer
Would you expect the mean to be higher or lower than the median? Explain.
Answer
Questions 4 to 7
The weights (pounds) of 14 people were recorded in Baishakh 2080. Draw a box and whisker plot.
190, 175, 187, 199, 205, 187, 176, 180, 187, 191, 200, 193, 188, 196
Answer
The marks of 15 students of Class 9 in a first terminal mathematics examination of 75 marks were:
61, 55, 54, 69, 74, 65, 58, 73, 71, 60, 66, 70, 56, 64, 73
Draw a box and whisker plot.
Answer
An IT company sells computers from two stores. The numbers sold over a year, month by month, were:
Store 1: 50, 460, 20, 160, 580, 250, 210, 120, 200, 510, 290, 380
Store 2: 520, 180, 260, 380, 80, 500, 630, 420, 210, 70, 440, 140
Draw box and whisker plots of the two stores on one scale and compare them.
Answer
Figure 5.25 shows the weights of dried dates. What percentage of the dates weigh more than 29 grams? Can this be found by looking at the box plot?
Answer
Practice every question in the book, and keep track of the ones you miss →
Project work
Back to the air
Here are Lalitpur’s twelve monthly averages of fine dust in 2023 (µg/m³), in ascending order:
13.7, 14.2, 14.8, 27.1, 30.9, 44.2, 44.4, 53.6, 74, 79, 79.7, 80.1
- The middle: ; the median, the 6.5th item, is .
- The quartiles: . and Q₃, the 9.75th item, = 74 + 0.75(79 − 74) = 77.75. So , coefficient .
- The deviations: the mean deviation from the mean is about 22.5 µg/m³ (coefficient 0.49), and the standard deviation µg/m³, so the C.V. is about 55%.
What it means: a coefficient of variation of 55% says that a typical month was more than half the mean away from it; the box covering almost the whole range says the year had no “usual” air, just a clean monsoon and a dirty dry season. One average, 46, hides that, and both halves of the story matter: the dry months are when people with weak lungs most need to take care, and they are also the months to work on, by cutting the smoke from kilns, vehicles and burning.
How the exam asks it
Grade 9’s final exam follows CDC’s Specification Grid and Model Question for Optional Mathematics, Grade 9 (2082). There Statistics has 7 marks of the 75 (10 teaching hours):
- Group A: one multiple-choice question, 1 mark (understanding).
- Statistics’ own question: one question in three parts, 3 marks (knowledge 1, understanding 1, higher ability 1).
- A question joining areas: parts of one question, 3 marks (application).
In the grid’s model paper the multiple-choice question shows a box plot of weights and asks for the lower quartile (read off the box’s left edge). Statistics’ own question gives a coffee shop’s customers over seven days, 15, 22, 18, 25, 20, 16, 23, and asks for the formula for the place of Q₃, then Q₃ itself (23, the 6th item in order), and then whether a standard deviation can be negative. And a question joining areas takes the function f(x) = 3x − 2 for x = 1, 2, 3, 4, 5, whose values are 1, 4, 7, 10 and 13, and asks for their standard deviation.
Where these facts come from
- Lalitpur’s 2023 monthly PM2.5 at Khumaltar (opening, Back to the air): as printed in CDC’s Optional Mathematics, Grade 9 (2082), 5.1; WHO’s 2021 guideline values for PM2.5, 15 µg/m³ for 24 hours and 5 µg/m³ for a year: WHO, “WHO global air quality guidelines” (2021) and its fact sheet, “Ambient (outdoor) air quality and health”, read November 2026.
- The Kathmandu Valley’s bowl shape, the shallow night-time layer that traps its smoke, its pollution’s main sources and the kilns’ season (activity in 5.1): M. Zhong and others, “Nepal Ambient Monitoring and Source Testing Experiment (NAMaSTE): emissions of particulate matter and sulfur dioxide from vehicles and brick kilns and their impacts on air quality in the Kathmandu Valley, Nepal”, Atmospheric Chemistry and Physics 19 (2019), 8209–8228; forest fires: Wikipedia, “Air pollution in Nepal”, read November 2026.
- The many rules for quartiles (fact in 5.1.2): Rob J. Hyndman and Yanan Fan, “Sample Quantiles in Statistical Packages”, The American Statistician 50 (1996), 361–365; Wikipedia, “Quantile” (Estimating quantiles from a sample), read November 2026.
- WHO’s child growth standards, about 8,500 children in six countries (fact in 5.1.4): WHO, “Child growth standards” and the WHO Multicentre Growth Reference Study, read November 2026.
- Karl Pearson, the name “standard deviation” (1893 lectures, 1894 paper) and the department of 1911; Fisher’s “variance” (1918) (story in 5.4): Wikipedia, “Standard deviation” (History), “Karl Pearson” and “Variance”, read November 2026; Jeff Miller, “Earliest Known Uses of Some of the Words of Mathematics” (“standard deviation”), read November 2026.
- John Tukey and the box plot (1970, 1977), the word “bit”, and Mary Eleanor Spear’s range bar (1952) (story in 5.5): Wikipedia, “Box plot” (History) and “John Tukey”, read November 2026.
- The exam’s Statistics questions (For the exam, How the exam asks it): CDC, Specification Grid and Model Question, Optional Mathematics, Grade 9 (2082), its table and model question paper.
- The unit follows CDC’s Optional Mathematics, Grade 9, Unit 5, pages 228–266, with the Nepali edition’s Exercise 5.5, Question 6.
A companion to your textbook, not a replacement for it: study from the book your school uses, and where the two differ, follow your teacher. Found a mistake? Please tell us.