
Every child in Nepal learns that the country has three belts, running from east to west: the Mountain belt along the Himalaya, the Hill belt in the middle, and the flat Terai in the south. Every one of the 77 districts belongs to one of them. Bhaktapur, where our science center is, is a Hill district.
In this unit you will build a program that learns the belts from real measurements of every district, and then guesses the belt of districts it has never seen. It does very well. But at one point it looks at Bhaktapur and says, quite confidently: Terai. By the end of the unit you will know exactly why it said that, what it tells us about Bhaktapur, and why that mistake is more useful than a hundred right answers.
In Grade 6 you trained a fruit sorter, and in Grade 7 you tested models fairly and caught them being one-sided. Then the model was inside a widget. Now you will write the whole model yourself, in Python, about twenty lines of it: you will measure how good it really is, choose what it looks at, and question where its data came from. Along the way you will see when this kind of AI is the right tool, when a simple rule does just as well, and what it costs the world when data is collected not from 77 districts but from billions of people.
The nearest-neighbor idea
Imagine a new student joins your class from another school, and you want to guess which of the school’s clubs she will like. You don’t know her yet. But you know which students she is most like: the same age, the same favorite subjects, the same games. If most of them are in the football club, football is a good guess.
That is the whole idea of the model in this unit, the one you met in Grade 6’s fruit sorter: to decide about something new, find the examples most like it, and give their answer. It is called the nearest-neighbor method, and the examples most like the new thing are its neighbors.
Recall from Grade 7 how a model sees an example: only as its features, the numbers measured about it, with a label, the right answer. For a district, the label is its belt. For features we will start with two:
- height: how high the district’s land is, in meters. A district’s land goes up and down, so we use its median height: if you sorted every spot of the district’s land from lowest to highest, the one in the middle. Half the land is lower, half higher.
- slope: how steep its land is, on average, in degrees. Flat fields have a slope near 0°; a steep hillside of terraced fields might be 30°.
Distance on a map of features
Two features put every district on a map, just as size and color put each fruit on Grade 6’s map: steepness across, height up. Districts that are alike sit close together on it. To find the nearest neighbors, a computer needs to measure how close two points are: their distance.
Measure the gap across (the difference in steepness) and the gap up (the difference in height). They are the two short sides of a right-angled triangle, and the distance is its long side. By the Pythagorean theorem from your mathematics class:
This straight-line distance is called the Euclidean distance, after Euclid, the Greek mathematician whose geometry it comes from. With three features, a third gap is squared and added under the square root, and so on for any number: a computer doesn’t need to draw the map to measure on it.
More than one neighbor
One neighbor can mislead: if the nearest example is odd, or has a wrong label, the answer is wrong too. So the model can ask several. With k nearest neighbors (often written k-NN), the model finds the k examples nearest the new thing and lets them vote: the label most of them have wins. k is a number we choose: 1, 3, 5…
In Figure 9.1, the three nearest neighbors of Bhaktapur are Dang (Terai), Kailali (Terai) and Udayapur (Hill). Two votes to one: Terai. That is the mistake from the start of the unit, and now you can see how it happened: on this map, Bhaktapur sits close to Terai districts. Why it does is the question for later.
The steps of k-nearest neighbors, as an algorithm:
Algorithm
Step 1: StartStep 2: Read the training examples, each with its features and labelStep 3: Read the new thing's features, and kStep 4: For each example, work out its distance from the new thingStep 5: Sort the examples from nearest to farthestStep 6: Take the first k, and count their labelsStep 7: Display the label with the most votes (if two tie, the one with the nearer example)Step 8: StopNotice what is missing: there is no training step. A nearest-neighbor model doesn’t work anything out in advance; it just keeps its examples and does all its work when a question comes. Its examples are the model. Other kinds of model, which you will meet later in this unit, do their work beforehand.
A model uses the 3 nearest neighbors. A new district’s neighbors are Hill, Mountain and Mountain. What does the model say?
Pick an answer to see why.
On a map of two features, a new point is 3 units across and 4 units up from an example. How far apart are they?
Pick an answer to see why.
Nepal’s districts as data
Here is the data for all 77 districts, as a CSV file, the kind you read in Unit 3: one row per district, its belt (the label), and four features. Besides height and slope there are two more, which you will try later: rain is how much rain falls in an average year, in millimeters, and people is the number of people living on each square kilometer.
districts.csv
district,belt,height,slope,rain,peopleAchham,Hill,1308,26,1987,135Arghakhanchi,Hill,990,21,2324,143Baglung,Hill,2235,28,2730,136Baitadi,Hill,1600,26,2245,162Bajhang,Mountain,3261,31,2272,55Bajura,Mountain,2827,30,1783,60Banke,Terai,188,5,1733,321Bara,Terai,118,3,1900,600Bardiya,Terai,180,6,1920,230Bhaktapur,Hill,1378,10,1745,3510Bhojpur,Hill,1296,23,1978,104Chitwan,Terai,260,8,2440,321Dadeldhura,Hill,1261,21,2146,93Dailekh,Hill,1425,26,1983,170Dang,Terai,593,12,1869,221Darchula,Mountain,3444,32,2561,49Dhading,Hill,1163,25,2780,171Dhankuta,Hill,1036,23,1789,168Dhanusha,Terai,102,2,1624,730Dolakha,Mountain,2690,28,2633,80Dolpa,Mountain,4798,28,1288,5Doti,Hill,1441,25,1999,100Gorkha,Hill,3183,30,2729,69Gulmi,Hill,1279,26,2252,222Humla,Mountain,4674,28,1282,9Ilam,Hill,1069,19,2634,166Jajarkot,Hill,2173,29,2018,85Jhapa,Terai,105,1,2605,622Jumla,Mountain,3443,26,1745,46Kailali,Terai,212,10,2154,275Kalikot,Mountain,2774,29,1678,89Kanchanpur,Terai,205,4,1963,318Kapilvastu,Terai,118,3,1898,414Kaski,Hill,2131,27,3630,288Kathmandu,Hill,1421,13,2137,4936Kavrepalanchok,Hill,1362,23,1878,261Khotang,Hill,1294,25,1869,110Lalitpur,Hill,1521,22,2111,1390Lamjung,Hill,1924,28,3479,94Mahottari,Terai,106,2,1724,706Makwanpur,Hill,668,18,2395,191Manang,Mountain,4933,30,2055,2Morang,Terai,108,5,2172,630Mugu,Mountain,4000,31,1382,20Mustang,Mountain,4734,24,792,4Myagdi,Hill,3160,32,3045,47Nawalpur,Terai,340,14,2497,265Nuwakot,Hill,1336,24,2748,221Okhaldhunga,Hill,1485,26,1982,130Palpa,Hill,990,23,2475,168Panchthar,Hill,1607,25,2474,138Parasi,Terai,117,5,2058,533Parbat,Hill,1393,24,2767,242Parsa,Terai,182,3,1930,465Pyuthan,Hill,1252,26,2095,176Ramechhap,Hill,1721,26,2361,109Rasuwa,Mountain,3746,31,3025,31Rautahat,Terai,98,2,1820,783Rolpa,Hill,1795,27,2069,125Rukum East,Hill,3066,31,2620,34Rukum West,Hill,1996,32,2640,137Rupandehi,Terai,115,3,1997,860Salyan,Hill,1300,22,1925,127Sankhuwasabha,Mountain,2625,29,3777,46Saptari,Terai,93,2,1651,551Sarlahi,Terai,110,3,1824,682Sindhuli,Hill,651,18,2060,121Sindhupalchok,Mountain,2239,28,3233,105Siraha,Terai,110,2,1547,649Solukhumbu,Mountain,4200,28,2347,31Sunsari,Terai,95,3,1820,778Surkhet,Hill,793,20,2054,167Syangja,Hill,984,22,2710,244Tanahun,Hill,647,20,2595,204Taplejung,Mountain,3781,29,3390,33Terhathum,Hill,1395,22,1713,132Udayapur,Hill,430,16,1691,148This is real data, put together for this book from four sources:
- belt: the government’s grouping of the districts into the three ecological belts, as the National Statistics Office uses it in the census: 16 Mountain, 40 Hill and 21 Terai districts.
- height and slope: worked out from a map of the height of the land made from space in the year 2000 (its story is later in the unit), in squares about 90 meters across. For each district we took the middle height of all its squares, and the average steepness between neighboring squares.
- rain: the average yearly rain from 1981 to 2010, from CHELSA, a free collection of climate maps made at a research institute in Switzerland.
- people: the population of each district in Nepal’s 2021 census, divided by the district’s area (measured on the same map).
Read it into a list of dictionaries, one per district, exactly as Unit 3 read the provinces. The function goes at the top of every program in this unit:
def read_districts(filename): """Return a list of dictionaries, one per district.""" file = open(filename) lines = file.read().splitlines() file.close() rows = [] for line in lines[1:]: p = line.split(",") rows.append({"district": p[0], "belt": p[1], "height": int(p[2]), "slope": int(p[3]), "rain": int(p[4]), "people": int(p[5])}) return rows rows = read_districts("districts.csv")print(len(rows), "districts")print(rows[9])counts = {}for row in rows: counts[row["belt"]] = counts.get(row["belt"], 0) + 1print(counts)Output
77 districts{'district': 'Bhaktapur', 'belt': 'Hill', 'height': 1378, 'slope': 10, 'rain': 1745, 'people': 3510}{'Hill': 40, 'Mountain': 16, 'Terai': 21}The tally (line 16 to 18, Unit 3’s pattern) checks that every row was read, and shows something to remember: the belts are not equal in size. Over half the districts are Hill districts.
In this data, what is a single example?
Pick an answer to see why.
A nearest-neighbor model in Python
The distance is a function: it squares the gap in each feature, adds them up, and takes the square root. math.sqrt(), from Python’s math module, gives a square root. Giving the function the list of features to use means the same function works for one feature, two or four.
Then, for a new district, the program makes a list of tuples, one per example: its distance, its name and its belt. Sorting a list of tuples sorts them by their first item, so after sort() the nearest is first. (If two first items are equal, Python compares the second items, and so on.) Here is Bhaktapur, with every other district as an example:
import math def read_districts(filename): """Return a list of dictionaries, one per district.""" file = open(filename) lines = file.read().splitlines() file.close() rows = [] for line in lines[1:]: p = line.split(",") rows.append({"district": p[0], "belt": p[1], "height": int(p[2]), "slope": int(p[3]), "rain": int(p[4]), "people": int(p[5])}) return rows def distance(a, b, features): """The straight-line distance between two rows, using these features.""" total = 0 for f in features: total = total + (a[f] - b[f]) ** 2 return math.sqrt(total) rows = read_districts("districts.csv")new = rows[9]others = rows[:9] + rows[10:]pairs = []for ex in others: pairs.append((distance(new, ex, ["height", "slope"]), ex["district"], ex["belt"]))pairs.sort()print("Nearest to", new["district"])for d, name, belt in pairs[:5]: print(round(d, 1), name, belt)Output
Nearest to Bhaktapur20.5 Parbat Hill20.6 Kavrepalanchok Hill20.8 Terhathum Hill43.1 Kathmandu Hill44.3 Nuwakot Hillrows[9] is Bhaktapur, and rows[:9] + rows[10:] is every other district, joined from two slices: a model must never count the new thing as its own example. Line 30 unpacks each tuple into three variables.
Its five nearest neighbors are all Hill districts, so the model says Hill. Right! But look at who they are: Parbat, Kavrepalanchok, Terhathum, Kathmandu, Nuwakot. They have one thing in common with Bhaktapur, a height of about 1,400 meters, and four of them are much steeper (22° to 24°, against Bhaktapur’s 10°). Did steepness count at all?
Scaling the features
Look at the sizes of the numbers. Heights run from 93 to 4,933 meters, so two districts’ heights often differ by hundreds. Slopes run only from 1° to 32°, so they can never differ by more than 31. In the distance, a gap of 100 meters counts exactly as much as a gap of 100 degrees, which is three times all the steepness there is. The height drowns out the slope. Parbat is “near” Bhaktapur because its height is only 15 meters different; the 14° gap in steepness hardly counts.
That is not what we meant. We wanted both features to count. The fix is to put every feature on the same scale before measuring: scaling. The simplest way, min–max scaling, turns each feature into a number from 0 to 1:
The lowest district gets 0, the highest gets 1, and one halfway between gets 0.5. Bhaktapur’s height becomes (1378 − 93) ÷ (4933 − 93) ≈ 0.27, and its slope (10 − 1) ÷ (32 − 1) ≈ 0.29. Now a gap of 0.1 means a tenth of the whole range for either feature.
The function scale() below adds a scaled copy of each feature to every row, under a new key: "height_s" beside "height". Then the same nearest-neighbor search runs on the scaled features:
import math def read_districts(filename): """Return a list of dictionaries, one per district.""" file = open(filename) lines = file.read().splitlines() file.close() rows = [] for line in lines[1:]: p = line.split(",") rows.append({"district": p[0], "belt": p[1], "height": int(p[2]), "slope": int(p[3]), "rain": int(p[4]), "people": int(p[5])}) return rows def distance(a, b, features): """The straight-line distance between two rows, using these features.""" total = 0 for f in features: total = total + (a[f] - b[f]) ** 2 return math.sqrt(total) def scale(rows, features): """Add each feature scaled from 0 to 1, as feature + "_s".""" for f in features: values = [] for row in rows: values.append(row[f]) low = min(values) high = max(values) for row in rows: row[f + "_s"] = (row[f] - low) / (high - low) rows = read_districts("districts.csv")scale(rows, ["height", "slope"])new = rows[9]others = rows[:9] + rows[10:]pairs = []for ex in others: pairs.append((distance(new, ex, ["height_s", "slope_s"]), ex["district"], ex["belt"]))pairs.sort()print("Nearest to", new["district"])for d, name, belt in pairs[:5]: print(round(d, 2), name, belt)Output
Nearest to Bhaktapur0.1 Kathmandu Hill0.17 Dang Terai0.24 Chitwan Terai0.24 Kailali Terai0.25 Nawalpur TeraiNow the nearest are Kathmandu (Hill), then Dang and Chitwan (Terai). With k = 3 the vote is two to one: Terai. Scaling made the slope count, and the slope says that Bhaktapur is flat. It is: most of Bhaktapur district is the floor of the Kathmandu Valley, an old lake bed of flat farmland, nearly as flat as the Terai. Its neighbors on the map are the Kathmandu Valley’s other flat district and the Terai districts that have some hills in them (Dang and Chitwan both have hills of the Chure range and valleys between).
So is scaling wrong? No. The model did exactly what we asked: it treated steepness as important. The mistake tells us something true about Bhaktapur, and something about our features: steepness alone can’t tell a valley in the hills from the plains. That is what models’ mistakes are for. We will decide which features to keep by testing, not by liking one answer.
Without scaling, why did slope hardly count in the distance?
Pick an answer to see why.
Training, testing and accuracy
How good is the model? You know from Grade 7 that you can’t judge it on its own examples: tested on a district it already has, the nearest example would be that same district, at a distance of 0, and it would always be right. So before anything else we split the data into a training set for the model to learn from and a test set to check it.
random.shuffle() mixes up a list’s items into a random order, like shuffling cards. Shuffle the districts, keep the first 15 for testing, and give the other 62 to the model. Then ask the model about each test district and count how often it is right: its accuracy.
import mathimport random def read_districts(filename): """Return a list of dictionaries, one per district.""" file = open(filename) lines = file.read().splitlines() file.close() rows = [] for line in lines[1:]: p = line.split(",") rows.append({"district": p[0], "belt": p[1], "height": int(p[2]), "slope": int(p[3]), "rain": int(p[4]), "people": int(p[5])}) return rows def scale(rows, features): """Add each feature scaled from 0 to 1, as feature + "_s".""" for f in features: values = [] for row in rows: values.append(row[f]) low = min(values) high = max(values) for row in rows: row[f + "_s"] = (row[f] - low) / (high - low) def distance(a, b, features): """The straight-line distance between two rows, using these features.""" total = 0 for f in features: total = total + (a[f] - b[f]) ** 2 return math.sqrt(total) def predict(new, examples, features, k): """The belt most of the k nearest examples have (a tie: the nearest's).""" pairs = [] for ex in examples: pairs.append((distance(new, ex, features), ex["belt"])) pairs.sort() votes = {} for d, belt in pairs[:k]: votes[belt] = votes.get(belt, 0) + 1 best = pairs[0][1] for belt in votes: if votes[belt] > votes[best]: best = belt return best rows = read_districts("districts.csv")scale(rows, ["height", "slope"])random.seed(8)random.shuffle(rows)test = rows[:15]train = rows[15:] features = ["height_s", "slope_s"]right = 0for row in test: guess = predict(row, train, features, 3) if guess == row["belt"]: right = right + 1 else: print("Wrong:", row["district"], "is", row["belt"], "but the model said", guess)print(right, "of", len(test), "right:", f"{round(100 * right / len(test))}%")Output
Wrong: Bhaktapur is Hill but the model said Terai14 of 15 right: 93%predict() is the whole model: lines 37 to 47 are the algorithm’s Steps 4 to 7. The vote is Unit 3’s tally. best starts as the nearest example’s belt, and changes only to a belt with more votes, so a tie goes to the nearest. random.seed(8) makes the shuffle the same every time the program runs, so you can compare runs (Unit 4). Change 3 to 1 or 5 on line 59 and run it again.
The model got 14 of the 15 test districts right: an accuracy of 93%. Its one mistake is Bhaktapur, as you expected.
The same model, on a map
The widget below is this model with the same 62 training districts and the same 15 test districts. The shading shows what it would say anywhere on the map: the color of the belt that wins the vote there.
Look at where the colors meet. The Terai is a tight group of dots at the bottom left: low and flat. Mountain and Hill overlap at the top right: Gorkha (Hill) is higher and steeper than Sindhupalchok (Mountain). No model using only these two features can get both right. When the examples of two labels are mixed together on the map, the mistakes there come from the data, not from the program.
One score is not enough
The score depends on which 15 districts happened to land in the test set. Change the seed in the program above to 1, 2, 3 and so on up to 10, and the accuracy with k = 3 comes out as 14, 12, 15, 14, 15, 15, 13, 14, 14 and 14 out of 15: anything from 80% to 100%. A test set of 15 is small, so its score is rough.
With only 77 districts, there is a better way: test every district, one at a time, with the other 76 as the training set. This is called leave-one-out testing. Each district is tested once, and never by a model that has it as an example. It is one kind of cross-validation: testing in turns, so that every example is used for testing and none is tested by a model that learned from it.
Leave-one-out also lets us ask two more questions. First, is 95% good? Compare it with a baseline: the score of the simplest possible guess. Most districts are Hill, so a “model” that always says Hill, without looking, is right 40 times in 77: 52%. A model must beat that before it has learned anything. Second, which belts does it get wrong? A confusion table counts, for each true belt, what the model said: the right answers are on the diagonal, and every other cell is one kind of mistake.
import math def read_districts(filename): """Return a list of dictionaries, one per district.""" file = open(filename) lines = file.read().splitlines() file.close() rows = [] for line in lines[1:]: p = line.split(",") rows.append({"district": p[0], "belt": p[1], "height": int(p[2]), "slope": int(p[3]), "rain": int(p[4]), "people": int(p[5])}) return rows def scale(rows, features): """Add each feature scaled from 0 to 1, as feature + "_s".""" for f in features: values = [] for row in rows: values.append(row[f]) low = min(values) high = max(values) for row in rows: row[f + "_s"] = (row[f] - low) / (high - low) def distance(a, b, features): """The straight-line distance between two rows, using these features.""" total = 0 for f in features: total = total + (a[f] - b[f]) ** 2 return math.sqrt(total) def predict(new, examples, features, k): """The belt most of the k nearest examples have (a tie: the nearest's).""" pairs = [] for ex in examples: pairs.append((distance(new, ex, features), ex["belt"])) pairs.sort() votes = {} for d, belt in pairs[:k]: votes[belt] = votes.get(belt, 0) + 1 best = pairs[0][1] for belt in votes: if votes[belt] > votes[best]: best = belt return best rows = read_districts("districts.csv")scale(rows, ["height", "slope"])features = ["height_s", "slope_s"]belts = ["Mountain", "Hill", "Terai"]table = {}for t in belts: for g in belts: table[(t, g)] = 0right = 0for i in range(len(rows)): others = rows[:i] + rows[i + 1:] guess = predict(rows[i], others, features, 3) table[(rows[i]["belt"], guess)] += 1 if guess == rows[i]["belt"]: right = right + 1print("Leave-one-out:", right, "of", len(rows), "right:", f"{round(100 * right / len(rows))}%")print("Always Hill:", 40, "of", len(rows), "right:", f"{round(100 * 40 / len(rows))}%")print()print("True belt said Mountain said Hill said Terai")for t in belts: print(f"{t:<10}{table[(t, 'Mountain')]:>14}{table[(t, 'Hill')]:>11}{table[(t, 'Terai')]:>12}")Output
Leave-one-out: 73 of 77 right: 95%Always Hill: 40 of 77 right: 52% True belt said Mountain said Hill said TeraiMountain 14 2 0Hill 1 38 1Terai 0 0 21A dictionary can have a tuple as its key: table[("Hill", "Terai")] counts the Hill districts the model called Terai. += 1 adds 1, short for table[...] = table[...] + 1. In the f-string, :<10 puts the belt’s name on the left of 10 places and :>14 puts a number on the right of 14, so the columns line up (Unit 4 used :>6).
The table shows the model’s character. It never mixes up Mountain and Terai: they are far apart on the map. Its four mistakes are all between belts that touch: two Mountain districts that sit among high Hill districts on the map (Bajhang and Sindhupalchok) called Hill, a high, steep Hill district (Myagdi) called Mountain, and a flat Hill district (Bhaktapur) called Terai. Accuracy alone, 95%, would have hidden all of that. In Grade 7 you found accuracy for each group of examples; a confusion table goes further and says which mistakes are made.
A model is right for 70 of 77 districts. A “model” that always says Hill is right for 40. What does the comparison show?
Pick an answer to see why.
Why does a model’s accuracy change when the data is split into training and test sets in a different random way?
Pick an answer to see why.
Choosing the features and k
We have two features, height and slope, and two more in the file, rain and people. More information should help, shouldn’t it? Test it. The program below works out the leave-one-out score for several sets of features, each with k = 1, 3 and 5. leave_one_out() is the loop from the last program, as a function.
import math def read_districts(filename): """Return a list of dictionaries, one per district.""" file = open(filename) lines = file.read().splitlines() file.close() rows = [] for line in lines[1:]: p = line.split(",") rows.append({"district": p[0], "belt": p[1], "height": int(p[2]), "slope": int(p[3]), "rain": int(p[4]), "people": int(p[5])}) return rows def scale(rows, features): """Add each feature scaled from 0 to 1, as feature + "_s".""" for f in features: values = [] for row in rows: values.append(row[f]) low = min(values) high = max(values) for row in rows: row[f + "_s"] = (row[f] - low) / (high - low) def distance(a, b, features): """The straight-line distance between two rows, using these features.""" total = 0 for f in features: total = total + (a[f] - b[f]) ** 2 return math.sqrt(total) def predict(new, examples, features, k): """The belt most of the k nearest examples have (a tie: the nearest's).""" pairs = [] for ex in examples: pairs.append((distance(new, ex, features), ex["belt"])) pairs.sort() votes = {} for d, belt in pairs[:k]: votes[belt] = votes.get(belt, 0) + 1 best = pairs[0][1] for belt in votes: if votes[belt] > votes[best]: best = belt return best def leave_one_out(rows, features, k): """How many rows the model gets right, each tested with all the others.""" right = 0 for i in range(len(rows)): others = rows[:i] + rows[i + 1:] if predict(rows[i], others, features, k) == rows[i]["belt"]: right = right + 1 return right rows = read_districts("districts.csv")scale(rows, ["height", "slope", "rain", "people"])tries = [["height"], ["slope"], ["height", "slope"], ["height", "rain"], ["height", "slope", "rain"], ["height", "slope", "people"]]print("Right out of 77 k=1 k=3 k=5")for features in tries: scaled = [] for f in features: scaled.append(f + "_s") line = f"{', '.join(features):<22}" for k in [1, 3, 5]: line = line + f"{leave_one_out(rows, scaled, k):5}" print(line)Output
Right out of 77 k=1 k=3 k=5height 72 73 70slope 53 58 57height, slope 71 73 69height, rain 70 64 67height, slope, rain 69 64 66height, slope, people 70 74 68Read the table row by row:
- Height alone is nearly as good as anything: 73 of 77 with k = 3. Height is what the belts are mostly about.
- Slope alone is poor, because a flat valley in the hills looks like the Terai. Together with height it adds nothing here: height and slope give 73 too.
- Adding rain makes it worse. Rain doesn’t change much between the belts (some of the wettest districts, Kaski and Lamjung, are Hill districts, and the driest, Mustang, is a Mountain district), so it adds a gap to every distance that has little to do with the belt. A feature that doesn’t change with the label is noise: it pulls in neighbors that are alike in the wrong way.
- People helps by one district at k = 3 (74 of 77), and not at all with k = 1 or 5. One district is too small a difference to trust (see the careful box above).
- k = 3 is best in every row without rain. One neighbor follows every odd example; five reach too far, out across the edge into the next belt. With rain in, every k does worse than without it.
So more features are not always better. Good features change with the label; each extra feature that doesn’t is a little more noise. Choosing them is called feature selection, and it is done by testing, as here, and by thinking about what the label really depends on.
Where the data came from
A model learns whatever its data says, mistakes and all. So before trusting a model, ask five questions about its data: where it came from (its source), how good it is (its quality), whether it covers everything the model will be used on (whether it is representative), whether it leans one way (bias), and whether it harms anyone’s privacy. Here they are for our districts.
Source. Each column has its own story, and you should be able to tell it.
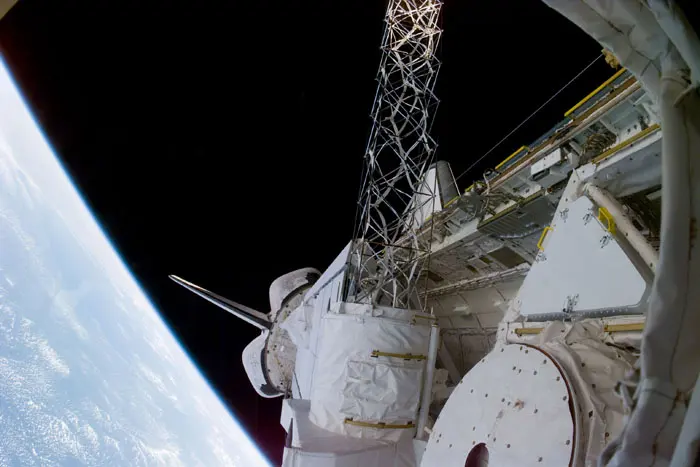
- The heights come from the Shuttle Radar Topography Mission. In February 2000 the US Space Shuttle Endeavour flew for 11 days with a radar that sent radio waves down at the ground from two antennas, one of them at the end of a 60-meter mast, and measured how they bounced back. From the tiny differences between the two echoes, computers worked out the height of almost all the land between 60° north and 56° south: about 80% of the Earth’s land.
- The rain was not measured in each place. It is an estimate made by a computer model of the world’s weather, worked out for every square kilometer and then corrected where there are rain gauges. Nepal has few rain gauges high in the mountains, so up there the numbers are mostly the model’s.
- The people come from the 2021 census, when the National Statistics Office counted every household in Nepal.
- The belts were decided by people: the government puts each whole district into one belt.
Quality. The heights are from the year 2000 and land hardly changes, so they are still good, but the radar couldn’t see into some steep, narrow valleys of the Himalaya, and those gaps were filled in later by estimating. Rain changes from year to year, and these are averages from 1981 to 2010; the climate has been changing since. People move, so the census numbers are already a few years old.
Representative? Our examples are whole districts, so the model is only fit for whole districts. Ask it about a single village and it has nothing to compare with: its examples never included anything as small. And there are only 77 examples, with just 16 Mountain districts. Any mistake moves the score by more than 1%.
Bias in the labels. The belt is a single word for a whole district, but a district’s land doesn’t stop at a belt’s edge. Gorkha is a Hill district, yet Manaslu, at 8,163 meters one of the highest mountains in the world, is inside it; more than half of Gorkha’s land is higher than 3,000 meters. The label isn’t wrong, it is a simplification made by people, for their own reasons (where most people live, how the district is run). A model can only learn the labels it is given: it learns the people’s decisions, not the land.
Privacy. Our file has no person in it: a district’s population is a total of thousands of people. The census asked every household about its members, but Nepal’s statistics law (the Statistics Act, 2079) forbids the office from publishing anything about a single person or family without their written permission. It publishes totals, and gives researchers only files with names, addresses and other identifying details taken out. Data about places is usually safe to share; data about people needs this care.
Our rain column is a computer model’s estimate, not rain measured in each district. Why does that matter for a model that learns from it?
Pick an answer to see why.
Which kind of AI?
Our model gets 95% of the districts right. Could something simpler do the same? Try a rule that a person could write after a glance at the data: below 500 meters, Terai; above 2,500 meters, Mountain; otherwise Hill.
def read_districts(filename): """Return a list of dictionaries, one per district.""" file = open(filename) lines = file.read().splitlines() file.close() rows = [] for line in lines[1:]: p = line.split(",") rows.append({"district": p[0], "belt": p[1], "height": int(p[2]), "slope": int(p[3]), "rain": int(p[4]), "people": int(p[5])}) return rows def rule(row): if row["height"] < 500: return "Terai" if row["height"] > 2500: return "Mountain" return "Hill" rows = read_districts("districts.csv")right = 0for row in rows: if rule(row) == row["belt"]: right = right + 1 else: print("Wrong:", row["district"], row["belt"], row["height"], "m")print(right, "of", len(rows), "right")Output
Wrong: Dang Terai 593 mWrong: Gorkha Hill 3183 mWrong: Myagdi Hill 3160 mWrong: Rukum East Hill 3066 mWrong: Sindhupalchok Mountain 2239 mWrong: Udayapur Hill 430 m71 of 77 rightA rule with two questions, 71 of 77: nearly as good as the model, and anyone can read exactly why it said what it said. But notice how the rule was made: the 500 and the 2,500 were chosen by looking at all 77 districts. A rule tuned on the data has seen the test, just like a model. And as soon as there are more than one or two features, nobody can find good cut-offs by eye, while a model finds its own.
So which to use depends on the job. Here are the main kinds you will meet:
| Kind | How it decides | Good when | Weak when |
|---|---|---|---|
| Rules written by people | if–then rules (Grade 8) | the rules are known, few and must be followed exactly; people must see why | nobody can say what the rules are |
| Nearest neighbors | copies its most similar examples | few features, a few thousand examples or fewer; you want to show which examples it copied | features need scaling; very many examples make every answer slow, since it compares with all of them |
| Decision tree | learns a chain of yes/no questions from the examples (“height above 2,450 m?”) | you want rules that people can read, but learned from data | it can learn odd questions from a few odd examples |
| Neural network | millions of numbers adjusted, bit by bit, during training (Grade 8’s image makers, Grade 10’s chatbots) | photos, sound, text: data with thousands of features nobody can choose by hand | needs huge data and a lot of electricity; nobody can read why it decided |
| Large language model | a very large neural network trained on text (Grade 8) | understanding and writing language in any words | can be confidently wrong; costly; not for exact answers |
To justify a choice, say what the task needs and match it: how much data there is, what kind (a table of a few numbers, or photos), whether a mistake is serious, whether people must be able to see why, and what it may cost. For our districts: a table of 77 rows and two to four numbers, where we want to see why each answer was given. A rule or nearest neighbors fits; a neural network would be like hiring a bus to carry one sack of rice.
Data on a huge scale
Our model learned from 77 rows that anyone can read in five minutes. The AI behind chatbots, face recognition and photo apps learns from billions of examples, collected from the internet and from the people who use it. Data on that scale brings benefits, and costs that 77 rows never would.
What it makes possible. Weather forecasting is one example. In November 2023, a team at Google DeepMind published GraphCast, a model that learned to forecast the weather from 39 years of the world’s weather records. It forecasts ten days ahead in under a minute on one computer, often more accurately than the best traditional forecast, which needs a supercomputer for hours. Better warnings of floods and storms save lives, in Nepal’s monsoon too. Models trained on huge collections of medical images help doctors find disease earlier, and translation tools let people read what they couldn’t before.
Consent and ownership. Much of the data is copied from the internet: websites, books, photos, videos, posted by people who never agreed to train AI with them. Writers, artists and newspapers have gone to court over it. Some companies collect even more personal things. Clearview AI, a company in the United States, copied photos of faces from the internet, more than 50 billion by its own count in 2024, to make a face search tool for police. In 2024 the Netherlands’ data protection authority fined it €30.5 million for building an illegal database of faces.
Surveillance. Once collected, data can be used for things nobody agreed to. Cameras that recognize faces can follow a person through a city; records of what you search and buy can be put together into a picture of your life (Grade 8’s data about you). The bigger the collection, the more harm if it leaks or is misused.
Hidden workers. Data needs labels, and labels come from people. Many of them work far from the companies whose AI they train, for low pay. In January 2023 TIME magazine reported that workers in Kenya, employed by an outsourcing company for OpenAI, were paid about US$1.32 to $2 an hour to read and label descriptions of violence and abuse, so that a chatbot could learn to avoid them. Some said the work harmed their mental health.
Bias at scale. In Grade 7 you saw photo collections where most photos came from a few rich countries, and voice collections with little Nepali. When data is collected from whoever is online most, the people who are online least, often the poorer, the older and the rural, are left out, and models work worse for them.
The environment. Storing and processing data on this scale runs in data centers, with electricity for the computers and water to cool them (Grade 8 looked at what one chatbot answer costs). The more data is kept and the bigger the models, the more power stations must run, and many still burn coal and gas.
Which of these is an environmental effect of collecting and processing data on a huge scale?
Pick an answer to see why.
Project
In short
Exercise
In this unit’s data, which is the label?
Pick an answer to see why.
A model uses k = 5. A new example’s five nearest neighbors are Terai, Hill, Terai, Hill, Terai. What does it say?
Pick an answer to see why.
Heights in a dataset run from 100 m to 5,100 m. What is a height of 2,600 m after min–max scaling?
Pick an answer to see why.
Why is a model never tested on its own training examples?
Pick an answer to see why.
Adding the rain feature made the district model worse. Why?
Pick an answer to see why.
Which task fits a neural network best?
Pick an answer to see why.
Explain, step by step, how a k-nearest-neighbor model with k = 3 decides the belt of a new district from its height and slope.
Answer
Work out the straight-line distance between these two scaled districts, and say which is nearer to A: B or C.
A: height 0.40, slope 0.70. B: height 0.70, slope 0.30. C: height 0.10, slope 0.80.
Answer
A student builds a nearest-neighbor model with two features: a person’s height in centimeters (140 to 190) and their monthly pocket money in rupees (0 to 5,000). What will go wrong, and how is it fixed?
Answer
A model is tested on 20 districts and gets 17 right. What is its accuracy? Its test set had 12 Hill, 5 Terai and 3 Mountain districts; what accuracy would a model that always says Hill get? What does the comparison tell you?
Answer
Copy and complete this confusion table for a model tested on 30 districts, then find its accuracy and say which mistake it makes most.
| True belt | said Mountain | said Hill | said Terai |
|---|---|---|---|
| Mountain | 5 | 2 | 0 |
| Hill | 3 | 13 | 1 |
| Terai | 0 | 0 | ? |
Answer
What is leave-one-out testing? Why is it useful for a small dataset like Nepal’s 77 districts?
Answer
The model calls Bhaktapur a Terai district. Explain why, and say whether this is a fault in the program, the features, or the label.
Answer
Evaluate the districts data set under five headings: source, quality, representativeness, bias and privacy. Give one point for each.
Answer
A bank in Nepal wants to decide who gets a loan with a model trained on its last 20 years of loans. Write three questions about the data the bank should ask, and why each matters.
Answer
For each task, choose rules written by people, nearest neighbors, or a neural network, and justify your choice: (i) deciding whether a student passes from their marks, using the school’s pass mark; (ii) guessing which of three kinds of rice a grain is, from its length and width, with 300 measured grains; (iii) turning a farmer’s spoken question in Nepali into text.
Answer
Describe two benefits and three harms of collecting data from billions of people to train AI.
Answer
Quiz yourself: Artificial intelligence, Grades 6–12 →
Practice every question in the book, and keep track of the ones you miss →