
Open the weather on a phone and it may say “70% chance of rain in Kathmandu tomorrow”. Nobody waited for tomorrow to find that out. Somewhere a computer ran a program that acted out the air over Nepal, hour by hour, many times over, and counted how often rain fell. The program didn’t contain the weather. It contained a model of the weather: a few rules about how air, heat and water behave, written in code.
In this unit you will build models of your own and run them. You will throw a cricket ball through the air, send the Earth round the Sun (and watch a simple method fling it into space), spread a flu through a district and stop it with vaccines, let leopards chase deer through the years, keep a room warm with a thermostat, and use thousands of random trials to answer questions no formula answers easily. Then comes the most important part: checking a model against real data from Nepal, and deciding how far its answers can be trusted.
What a model is
A map of Bhaktapur is a model of Bhaktapur. It shows the streets, the squares and the temples, and where each is. It leaves out almost everything else: the people, the noise, the smell of the bakeries, the color of each house. That is not a fault. A map that showed everything would be as big as Bhaktapur, and useless. A map is good because it keeps exactly what a walker needs and leaves out the rest.
A model is a simplified description of a real system that keeps what matters for a question and leaves out the rest. Choosing what to keep and what to leave out is abstraction, the same idea you met when you wrote functions: the details are hidden, and only what is needed is left.
Every model rests on assumptions: things it takes to be true, or true enough, without checking them inside the model. A model of a thrown cricket ball might assume the ground is flat, the air is still, and the ball doesn’t spin. Writing the assumptions down is part of building the model, because when a model gives a wrong answer, a wrong assumption is the first thing to suspect.
| A model of a thrown cricket ball | |
|---|---|
| Keeps | where the ball is; how fast it is going, and in which direction; gravity; the air pushing back against it |
| Leaves out | wind; the ball’s spin and its seam; the height of the thrower’s hand; the curve of the Earth |
| Assumes | the ground is flat; gravity is the same everywhere on the field; the air is the same all the way up |
| Parameters | the throw’s speed and angle; the ball’s mass and size; how thick the air is |
As in Grade 10, the numbers a model takes as its settings are its parameters. Change a parameter and the same model describes a different throw, a different disease, a different planet.
A simulation is a model run forward in time: a program that starts from how things are now and works out, step by step, how they will be a moment later, then a moment after that. Grade 10’s ticket counter was one. In this unit you will build simulations of things that move, things that spread and things that grow.
A model of a bus route from Bhaktapur to Ratnapark keeps the stops, the distances and the usual time between stops. Which is an assumption of this model?
Pick an answer to see why.
Why is leaving things out of a model often a good thing?
Pick an answer to see why.
A thrown ball, one step at a time
A fielder on the boundary throws the ball towards the wicketkeeper. Where will it land? The ball’s path depends on its speed, which changes all the time: gravity pulls it down, and the air pushes back against it. Questions like this, where how things change depends on how they are now, are exactly what simulations are for.
The update rule
The trick is to cut time into small pieces. Choose a time step, a short time like half a second, written dt (for “a little bit of time”). The model’s state is everything it needs to know about the ball at one moment: where it is (x across, y up) and how fast it is moving across and up (vx and vy, its velocity). Then repeat an update rule that turns the state now into the state one time step later:
- Move the ball. In a time
dtat speedvx, it goesvx × dtacross, andvy × dtup. - Change its velocity. Gravity makes the ball fall 9.8 m/s faster every second, so in a time
dtits speed up falls by9.8 × dt. Nothing changes its speed across (for now: there is no air yet).
This way of stepping forward, using the speeds as they are at the start of each step, is called Euler’s method, after the Swiss mathematician Leonhard Euler, who described it in a book of 1768. Here it is, for a strong throw of 25 m/s at 45°, with a time step of half a second:
import math g = 9.8 # gravity: 9.8 m/s faster down, every seconddt = 0.5 # the time step, in secondsx, y = 0.0, 0.0 # where the ball is (meters)vx = 25 * math.cos(math.radians(45)) # its speed across (m/s)vy = 25 * math.sin(math.radians(45)) # its speed up (m/s)t = 0.0 print(" t x y")while y >= 0: print(f"{t:3.1f} {x:6.1f} {y:6.1f}") x = x + vx * dt # move, at the speed it has now y = y + vy * dt vy = vy - g * dt # gravity changes the speed up t = t + dtprint(f"Below the ground at t = {t:.1f} s, {x:.1f} m away")Output
t x y0.0 0.0 0.00.5 8.8 8.81.0 17.7 15.21.5 26.5 19.22.0 35.4 20.72.5 44.2 19.73.0 53.0 16.33.5 61.9 10.44.0 70.7 2.1Below the ground at t = 4.5 s, 79.5 m awaymath.cosandmath.sinsplit the throw’s speed into its part across and its part up (math.radians(45)turns 45° into the units they use). At 45° the two parts are equal, about 17.7 m/s each.- The ball rises, slows, turns over at about 2 seconds and falls. Each row is the ball’s state, one time step after the row above: a list of states like this is the simulation’s output, its simulated data.
- The loop stops the first time the ball is below the ground. It really landed somewhere between the last two rows; the program reports the first point found underground.
In the update rule, why does vy change each step but vx doesn’t?
Pick an answer to see why.
How big a step?
The program said the ball lands about 79.5 m away. For this one case, a throw with no air that lands at the height it started, physics gives an exact formula: distance = speed² × sin(2 × angle) ÷ 9.8. At 45°, sin 90° is 1, so the ball lands 25² ÷ 9.8 = 63.8 m away. The simulation was 16 m out. Why?
In each time step, the program moved the ball at the speed it had at the start of the step, as if that speed stayed the same for the whole half second. But it doesn’t: the ball slows as it rises. So each step carries the ball a little too high, and the errors add up. Half a second is a long time for a ball that is only in the air for about 3.6 seconds.
So make the step smaller. Here the update rule is a function in a module, so it can be run many times with different settings. It also has room for the air, which comes next; for now drag is 0, no air:
ball.py
"""A ball thrown from the ground, moved one time step at a time.""" import math def throw(speed, angle, dt, drag=0.0): """Gives back how far the ball lands (m), how high it goes (m) and its time in the air (s).""" g = 9.8 x, y, t, top = 0.0, 0.0, 0.0, 0.0 vx = speed * math.cos(math.radians(angle)) vy = speed * math.sin(math.radians(angle)) while y >= 0: v = math.sqrt(vx * vx + vy * vy) # the ball's speed ax = -drag * v * vx # the air pushes back... ay = -g - drag * v * vy # ...and gravity pulls down x = x + vx * dt y = y + vy * dt vx = vx + ax * dt vy = vy + ay * dt t = t + dt top = max(top, y) return x, top, tax and ay are the ball’s acceleration: how fast its velocity changes, across and up. With drag=0.0, ax is 0 and ay is −9.8, exactly the update rule above. Now try smaller and smaller steps:
import ball exact = 25 ** 2 / 9.8 # the formula, for 45° and no airprint(f"Formula: {exact:.2f} m")for dt in [0.5, 0.2, 0.1, 0.01, 0.001]: distance, top, t = ball.throw(25, 45, dt) print(f"step {dt:5} s: {distance:6.2f} m, off by {distance - exact:5.2f} m")Output
Formula: 63.78 mstep 0.5 s: 79.55 m, off by 15.77 mstep 0.2 s: 70.71 m, off by 6.94 mstep 0.1 s: 67.18 m, off by 3.40 mstep 0.01 s: 63.99 m, off by 0.22 mstep 0.001 s: 63.80 m, off by 0.02 mLook at the last column. Make the step 10 times smaller, and the error gets about 10 times smaller too. This is the time-step error (or step error): the error that comes from pretending things stay the same during a step. For Euler’s method it shrinks in proportion to the step. But a smaller step costs more work: a step of 0.001 s needs about 3,600 steps for this throw, 400 times as many as the 9 steps of 0.5 s. Every simulation is a choice between a small step (more accurate, slower) and a big one (quicker, less accurate).
A simulation with a time step of 0.1 s is off by 3.4 m. With Euler’s method, about how far off will it be with a step of 0.01 s?
Pick an answer to see why.
Adding the air
Put your hand out of the window of a moving bus and you feel the air push it back, harder the faster the bus goes. A ball feels the same push, called air resistance or drag. For a ball moving as fast as a throw, the push grows with the square of its speed: twice as fast, four times the push. It acts against the way the ball is moving, so it slows the ball across and up.
Physics gives drag’s size: half × the air’s density × a number for the ball’s shape, its drag coefficient (about 0.5 for a cricket ball, measured in wind tunnels: a little less for a new ball, more for a worn one) × the ball’s area seen from the front × its speed². To get the slowing, divide by the ball’s mass. All of that except the speed can be worked out once and kept in one number, drag. In ball.py the slowing is drag × v², split into its parts across and up by multiplying by vx / v and vy / v (the ball’s direction): that gives drag × v × vx and drag × v × vy.
import mathimport ball # a cricket ball: 0.16 kg, 7.2 cm across; air near sea level, 1.2 kg/m³mass, width, air, shape = 0.16, 0.072, 1.2, 0.5area = math.pi * (width / 2) ** 2drag = 0.5 * air * shape * area / massprint(f"drag = {drag:.5f} per meter")for angle in range(20, 61, 5): no_air = ball.throw(25, angle, 0.001)[0] with_air = ball.throw(25, angle, 0.001, drag)[0] print(f"{angle}°: {no_air:5.1f} m with no air, {with_air:5.1f} m with air")Output
drag = 0.00763 per meter20°: 41.0 m with no air, 34.1 m with air25°: 48.9 m with no air, 39.2 m with air30°: 55.3 m with no air, 43.1 m with air35°: 60.0 m with no air, 45.7 m with air40°: 62.8 m with no air, 47.0 m with air45°: 63.8 m with no air, 47.0 m with air50°: 62.8 m with no air, 45.8 m with air55°: 60.0 m with no air, 43.5 m with air60°: 55.3 m with no air, 39.9 m with airTwo things to notice. The air takes away about a quarter of the distance: 47 m, not 64. And the best angle is no longer 45°. With no air, 40° and 50° do equally well, and 45° is best. With air, 40° does better than 50°, and the best throw is lower than 45°: a high throw spends longer in the air, so the air has longer to slow it. This is a result there is no simple formula for. The simulation found it with a loop.
With air resistance in the model, why is the best angle for a long throw lower than 45°?
Pick an answer to see why.
A planet’s orbit, and why the simple method drifts
The same idea, a state and an update rule, can follow the Earth round the Sun. The only force on the Earth that matters here is the Sun’s gravity: a pull straight towards the Sun, which gets weaker with distance. Twice as far, a quarter of the pull: the pull is in proportion to 1 ÷ distance².
The pull of the Sun
To keep the numbers small, measure distance in astronomical units (AU): 1 AU is the Earth’s distance from the Sun, about 150 million km. Measure time in years. In these units the Earth goes once round a circle of radius 1, a distance of 2π AU, in 1 year, so its speed is 2π AU a year, and the Sun’s pull at distance r is 4π² ÷ r². (The number 4π² comes from those two facts; physics calls it GM, the strength of the Sun’s gravity.)
The pull points from the Earth to the Sun, which sits at (0, 0). Dividing x and y by the distance r gives that direction, so the pull’s parts are -GM * x / r**3 across and -GM * y / r**3 up (r**3 because it is / r**2 for the size and / r for the direction). Start the Earth at (1, 0), moving straight up at 2π AU a year, and step forward one day at a time. Here is the update rule two ways: Euler’s, as for the ball, and with the two halves the other way round:
import math GM = 4 * math.pi ** 2 # the Sun's pull, in AU and yearsdt = 1 / 365.25 # one day, in years def orbit(years, velocity_first): """Follows the Earth round the Sun. Gives back its distance from the Sun at the end (AU).""" x, y = 1.0, 0.0 # 1 AU from the Sun vx, vy = 0.0, 2 * math.pi # moving 2π AU a year, at right angles to the Sun for step in range(round(years / dt)): r = math.sqrt(x * x + y * y) ax = -GM * x / r ** 3 # the pull: GM/r², towards the Sun ay = -GM * y / r ** 3 if velocity_first: # change the velocity, then move vx = vx + ax * dt vy = vy + ay * dt x = x + vx * dt y = y + vy * dt else: # move, then change the velocity (Euler) x = x + vx * dt y = y + vy * dt vx = vx + ax * dt vy = vy + ay * dt return math.sqrt(x * x + y * y) for years in [1, 2, 5, 10]: euler = orbit(years, False) cromer = orbit(years, True) print(f"after {years:2} years: Euler {euler:.3f} AU, velocity first {cromer:.4f} AU")Output
after 1 years: Euler 1.206 AU, velocity first 1.0000 AUafter 2 years: Euler 1.349 AU, velocity first 1.0001 AUafter 5 years: Euler 1.563 AU, velocity first 1.0001 AUafter 10 years: Euler 1.895 AU, velocity first 1.0001 AUThe real Earth has stayed about 1 AU from the Sun for billions of years. With Euler’s method, even with steps of only one day, the Earth spirals outwards: after 10 years it is almost twice as far from the Sun, beyond the orbit of Mars. Swap two pairs of lines, and it stays on its orbit.
Small errors that add up
Why does Euler’s method push the Earth outwards? Look at one step (Figure 5.2). At the start of the step the Earth is moving along its orbit, at right angles to the Sun. Euler moves it in a straight line, the way it is going now, for the whole step. But a straight line that just touches a circle lies outside the circle everywhere else. So every step lands the Earth a little outside its orbit. There, the Sun’s pull is weaker, and Euler has already given it the speed it had closer in, so it climbs a little further next time. No step is far wrong, but every error is in the same direction, and they never cancel. After thousands of steps the small errors have added up to a different orbit. A slow, steady error like this is called drift.
The ball had the same kind of error, but its flight was over in a few seconds, before the error could grow. An orbit goes round and round for ever, and a simulation of it runs for thousands or millions of steps. A method that is good enough for a short flight can be useless for a long one.
A small change that fixes it
The fix in the program above is called the Euler–Cromer method, after the physicist Alan Cromer, who explained in 1981 why it works so well: change the velocity first, then move with the new velocity. On the orbit, the new velocity has already been turned a little towards the Sun, so each step leans inwards instead of running straight on along the old direction. Its errors no longer all push the same way: over a whole orbit, the errors outwards and inwards balance, so the Earth stays on its orbit, round after round. It isn’t exact (each orbit wobbles a little, and the orbit slowly turns), but it doesn’t drift.
Why does Euler’s method make a simulated planet spiral outwards?
Pick an answer to see why.
What is the only difference between Euler’s method and the Euler–Cromer method in the program?
Pick an answer to see why.
An epidemic in code
A student comes back to a school hostel with flu. A few days later, three of her friends have it; a week later, half the hostel. Then, just as it seems everyone will catch it, the new cases slow down and stop, and some students never catch it at all. Why does an epidemic stop before everyone is ill? A model can show you.
Three groups
The best-known model of an epidemic sorts everyone into three groups:
- S, susceptible: people who haven’t had the disease, and can catch it.
- I, infected: people who have it now, and can pass it on.
- R, recovered: people who have had it, got better, and can’t catch it again (for a while, at least).
It is called the SIR model. Each day, people move from S to I to R, and never back:
- Each infected person passes the disease to a few people a day, but only those who are still susceptible catch it. If a third of the people are susceptible, only a third of their meetings can pass it on. So the new cases in a day are
spread × S × I ÷ people, wherespreadis how many people one infected person would infect each day if everyone were susceptible. - Each day, some of the infected get better: with a disease that lasts about 7 days, about 1 in 7 of them,
I ÷ 7.
The most important number of an epidemic is the basic reproduction number, R₀ (“R nought”): how many people one infected person infects, on average, in a population where everyone can catch it. It is spread × days sick. For flu it is usually between 1 and 2; for measles, one of the most catching diseases known, it is about 12 to 18. If R₀ is above 1, each case makes more than one new case, and the disease spreads; below 1, it dies out.
Here is the model for Bhaktapur district’s 432,132 people (the 2021 census), starting with 10 people ill, for a disease with R₀ of 2.5 that lasts 7 days:
people = 432132 # Bhaktapur district, 2021 censusinfected = 10recovered = 0susceptible = people - infected - recoveredr0 = 2.5days_sick = 7spread = r0 / days_sick # people infected per infected person per day, if all susceptible peak, peak_day = 0, 0print("day susceptible infected recovered")for day in range(1, 181): new_cases = spread * susceptible * infected / people new_recoveries = infected / days_sick susceptible = susceptible - new_cases infected = infected + new_cases - new_recoveries recovered = recovered + new_recoveries if infected > peak: peak, peak_day = infected, day if day % 30 == 0: print(f"{day:3} {susceptible:12,.0f} {infected:9,.0f} {recovered:10,.0f}") print(f"Most ill at once: {peak:,.0f} people, on day {peak_day}")print(f"Never caught it: {susceptible:,.0f} people ({100 * susceptible / people:.0f}%)")Output
day susceptible infected recovered 30 426,573 3,326 2,233 60 115,745 96,280 220,106 90 44,138 5,357 382,637120 42,405 177 389,550150 42,350 6 389,777180 42,348 0 389,784Most ill at once: 105,651 people, on day 56Never caught it: 42,348 people (10%)({peak:,.0f} prints a number with commas between the thousands and no decimal places.) For a month almost nothing seems to happen: about 3,000 ill in a district of 432,000. Then, in the second month, it explodes, and at its peak a quarter of the district is ill at once. And then it stops, with 10% of the people never having caught it. Why? Because by then most people have had it. Each infected person still meets as many people, but most of them can’t catch it any more, so each case makes fewer than one new case, and the epidemic dies away.
Herd immunity
Now suppose that before the disease arrives, some people are vaccinated. They start in R: they can’t catch it, and they can’t pass it on. Each infected person then meets fewer people who can catch it. If enough are immune, each case makes fewer than one new case from the very start, and the disease can’t spread at all, even to the people who aren’t vaccinated. That is herd immunity: the immune protect the others by standing in the disease’s way.
How many is enough? Each case infects R₀ people when all can catch it, and R₀ × (the share still susceptible) when some are immune. That must be below 1, so the share immune must be above 1 − 1 ÷ R₀. For R₀ = 2.5 that is 1 − 0.4 = 60%. Check it with the model:
def epidemic(r0, vaccinated, people=432132, days_sick=7): """The SIR model for a year. Gives back how many people catch the disease.""" infected = 10 recovered = vaccinated * people # the vaccinated start immune susceptible = people - infected - recovered spread = r0 / days_sick caught = infected for day in range(365): new_cases = spread * susceptible * infected / people susceptible = susceptible - new_cases infected = infected + new_cases - infected / days_sick caught = caught + new_cases return caught for share in [0, 0.2, 0.4, 0.5, 0.55, 0.6, 0.7]: print(f"{100 * share:3.0f}% vaccinated: {epidemic(2.5, share):9,.0f} people catch it")Output
0% vaccinated: 389,784 people catch it 20% vaccinated: 278,296 people catch it 40% vaccinated: 152,280 people catch it 50% vaccinated: 80,063 people catch it 55% vaccinated: 23,955 people catch it 60% vaccinated: 517 people catch it 70% vaccinated: 40 people catch itVaccinating 20% of people saves more than 20% from the disease: it saves over 111,000, the vaccinated and many others. Near 60% the cases collapse, from tens of thousands to a few hundred. Above it, the 10 people who brought the disease in pass it to a handful, and it dies out.
A disease has R₀ = 4. What share of people must be immune for herd immunity?
Pick an answer to see why.
In the SIR model, why does an epidemic stop before everyone has caught it?
Pick an answer to see why.
Predator and prey
High in the mountains of Dolpa and Mustang, snow leopards hunt blue sheep (naur). When there are plenty of blue sheep, the leopards eat well, raise more cubs, and their numbers grow. But more leopards eat more sheep, and the sheep become fewer. Then food is scarce, fewer cubs survive, and the leopards become fewer. With fewer hunters, the sheep can recover, and it could all begin again. Real mountains are more complicated (snow leopards also eat marmots, and the herders’ goats and yaks), but each depends on the other: a change in one changes the other, which changes the first. What would rules like these do to the two numbers, year after year? A model can show you.
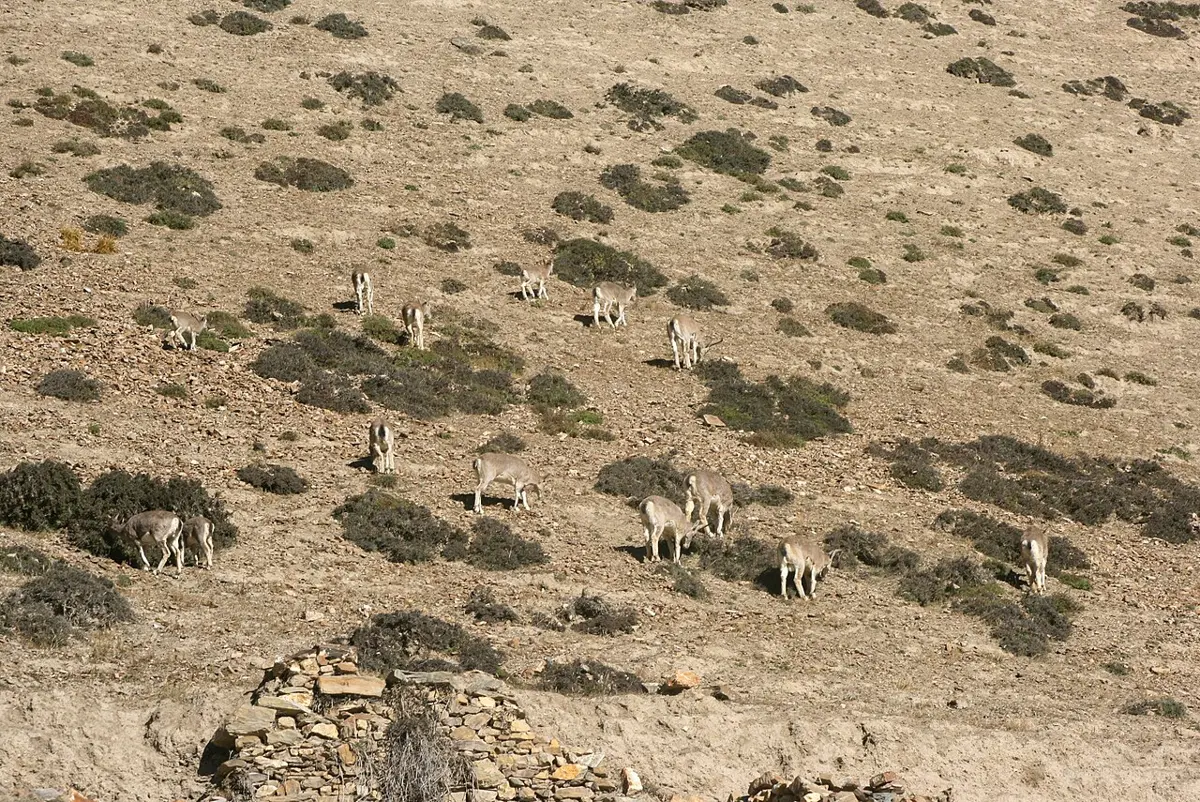
A model of this, as simple as possible, keeps two numbers, the prey and the predators, and four rules:
- The prey are born,
births × preya year, when there is plenty of grass. - The prey are eaten,
eaten × prey × predatorsa year: more prey and more predators mean more meetings. - The predators raise young in proportion to what they eat,
fed × prey × predators. - The predators die,
deaths × predatorsa year.
This is the Lotka–Volterra model, worked out by Alfred Lotka in the United States in 1925 and, on his own, by Vito Volterra in Italy in 1926. Volterra was trying to explain a puzzle brought to him by the biologist Umberto D’Ancona: during World War I, when fishing in the Adriatic Sea almost stopped, the share of sharks and other hunting fish in the catch went up.
In this program the animals are counted in hundreds, and every number in it is made up to show the idea: the starting numbers and the four parameters weren’t measured in any real valley (snow leopards are rare: no valley holds thousands of them):
prey, predators = 40.0, 10.0 # hundreds of animalsbirths, eaten, fed, deaths = 1.0, 0.05, 0.01, 0.8dt = 0.001 # years for step in range(1, 16001): new_prey = births * prey - eaten * prey * predators new_predators = fed * prey * predators - deaths * predators prey = prey + new_prey * dt predators = predators + new_predators * dt if step % 2000 == 0: print(f"year {step * dt:4.0f}: prey {prey:6.1f}, predators {predators:5.1f}")Output
year 2: prey 129.2, predators 9.1year 4: prey 100.7, predators 40.8year 6: prey 26.5, predators 20.8year 8: prey 52.6, predators 8.4year 10: prey 163.7, predators 12.8year 12: prey 58.6, predators 40.4year 14: prey 27.6, predators 15.9year 16: prey 71.3, predators 7.6The numbers rise and fall in turn, about every seven and a half years: first the prey, then, a year or two later, the predators. Neither settles down. Nobody wrote “go round in cycles” in the program; the cycles come out of four simple rules acting on each other. Behavior that comes out of simple rules like this, without being written in, is said to emerge.
In the predator–prey model, what happens to the predators a little after the prey reach their highest number?
Pick an answer to see why.
A model that steers itself
On a winter night in Kathmandu, a room heater with a thermostat keeps a room warm without anyone touching it. It switches itself on when the room is cold and off when it is warm. The overhead water tank on many houses in Nepal does the same with its pump: an automatic controller starts the motor when the water is low and stops it when the tank is full. These are models of a different kind: a system that measures what it is doing and corrects itself.
Every such system has three parts:
- a sensor, which measures the thing to be controlled: the thermostat’s thermometer, the tank’s float;
- a controller, which compares the measurement with the set point, the value wanted (20 °C, a full tank), and decides what to do;
- an actuator, which does it: the heater, the pump.
What the actuator does changes what the sensor measures next, which changes what the controller decides. This loop is called feedback, and a system that steers itself by it is a control system. The predator and prey were a feedback loop too, but nobody chose their set point.
A room, a heater and a thermostat
Here is a model of a room on a cold night, in a module, heating.py. Its state is three temperatures: the heater’s own, the room’s air, and the thermostat’s. Heat flows from the heater into the air, from the air into the thermostat, and out through the walls into the night. Each change follows one simple rule: a thing warms or cools in proportion to how much hotter or colder its neighbor is, so heat flows fastest when the difference is biggest. Every number in it is made up to behave like a small room; none was measured.
heating.py
"""A room with a heater and a thermostat, moved one time step at a time.""" OUTSIDE = 5.0 # a winter night outside, °C def step(heater, room, sensor, power, dt): """The heater's, the air's and the thermostat's temperatures (°C), dt minutes later. power is how hard the heater works: 0 is off, 1 is full.""" heater_change = 1.0 * power - 0.2 * (heater - room) # warmed by its power; warms the air room_change = 0.1 * (heater - room) - 0.02 * (room - OUTSIDE) # warmed by the heater; cooled by the walls sensor_change = 0.2 * (room - sensor) # the thermostat follows the air, slowly return heater + heater_change * dt, room + room_change * dt, sensor + sensor_change * dtIt is Euler’s method again, with a time step of a tenth of a minute. Even at full power this heater can’t warm the room above 30 °C, as a real small heater in a cold room can’t warm it without limit.
On or off: a thermostat
The simplest controller is on/off: the heater is either on, at full power, or off. A thermostat that switched exactly at 20 °C would click on and off many times a minute as the temperature wobbled across 20, and soon wear its switch out. So a real one leaves a gap, a dead band: here it switches on below 19.5 °C and off above 20.5 °C. The program prints each moment the heater is switched, then draws the room’s temperature for four hours.
import matplotlib.pyplot as pltimport heating target = 20.0 # the set point, °Cdt = 0.1 # the time step, in minutesheater = room = sensor = 10.0 # a cold room, with the heater offon = False times, temps = [], []for step in range(2401): # 240 minutes: 4 hours t = step * dt was_on = on if sensor < target - 0.5: # the controller reads the sensor... on = True elif sensor > target + 0.5: on = False # ...and switches the heater if on != was_on: print(f"{t:5.1f} min: thermostat {sensor:.1f} °C, room {room:.1f} °C: heater {'on' if on else 'off'}") power = 1.0 if on else 0.0 heater, room, sensor = heating.step(heater, room, sensor, power, dt) times.append(t) temps.append(room) later = temps[600:] # after the first hourprint(f"After the first hour: from {min(later):.1f} to {max(later):.1f} °C") plt.plot(times, temps, label="room")plt.axhline(target, color="gray", linestyle="--", label="set point")plt.xlabel("Minutes")plt.ylabel("Temperature (°C)")plt.title("A room with an on/off thermostat")plt.legend()plt.show()Output
0.0 min: thermostat 10.0 °C, room 10.0 °C: heater on 66.9 min: thermostat 20.5 °C, room 21.1 °C: heater off 84.7 min: thermostat 19.5 °C, room 18.7 °C: heater on110.4 min: thermostat 20.5 °C, room 21.1 °C: heater off128.0 min: thermostat 19.5 °C, room 18.7 °C: heater on153.6 min: thermostat 20.5 °C, room 21.1 °C: heater off171.2 min: thermostat 19.5 °C, room 18.7 °C: heater on196.8 min: thermostat 20.5 °C, room 21.1 °C: heater off214.4 min: thermostat 19.5 °C, room 18.7 °C: heater on240.0 min: thermostat 20.5 °C, room 21.1 °C: heater offAfter the first hour: from 18.5 to 21.2 °CPress Run to see the chart: the room warms for an hour, then swings up and down around 20 °C for as long as the program runs, once about every 43 minutes. A rise and fall that repeats like this is an oscillation. Look also at how far it swings. The thermostat switches at 19.5 and 20.5 °C, but the room goes from 18.5 to 21.2 °C. When the heater is switched off it is still hot, so it goes on warming the air; and the thermostat, which warms more slowly than the air, reads 20.5 °C only when the air is already at 21.1 °C. The room goes past the point where it should have stopped: an overshoot. Delays in a loop cause overshoot, and the longer the delay, the bigger it is.
More power the colder it is: a proportional controller
An on/off controller only knows “too cold” or “too warm”. A better one gives more power the farther the room is from the set point: full power when it is very cold, a little when it is nearly right. This is a proportional controller:
power = gain × (set point − temperature)
The gain says how strongly it reacts: with a gain of 0.2, a room 5 °C too cold gets 0.2 × 5 = 1, full power. The heater needs a dial for this, not just a switch, as an inverter air conditioner has: it runs its compressor faster or slower instead of only on and off. Here are three gains:
import matplotlib.pyplot as pltimport heating target = 20.0dt = 0.1 def run(gain): """Four hours with a proportional controller. Gives back the room's temperatures.""" heater = room = sensor = 10.0 temps = [] for step in range(2400): power = gain * (target - sensor) # more power the colder it is power = max(0.0, min(1.0, power)) # but never below off or above full heater, room, sensor = heating.step(heater, room, sensor, power, dt) temps.append(room) return temps for gain in [0.2, 1, 3]: temps = run(gain) last = temps[-600:] # the last hour print(f"gain {gain}: highest {max(temps):.1f} °C; last hour from {min(last):.1f} to {max(last):.1f} °C") plt.plot([i * dt for i in range(len(temps))], temps, label=f"gain {gain}") plt.axhline(target, color="gray", linestyle="--", label="set point")plt.xlabel("Minutes")plt.ylabel("Room temperature (°C)")plt.title("A room with a proportional controller")plt.legend()plt.show()Output
gain 0.2: highest 17.8 °C; last hour from 17.5 to 17.5 °Cgain 1: highest 20.2 °C; last hour from 19.4 to 19.5 °Cgain 3: highest 20.6 °C; last hour from 19.1 to 20.4 °CRun it and compare the three lines.
- Gain 0.2 never reaches the set point at all. It settles at 17.5 °C, 2.5 °C short. Holding a room at 17.5 °C on a cold night takes half the heater’s power, and this controller gives power only when the room is too cold: 0.2 × 2.5 = 0.5. So the room settles exactly where the error is big enough to call for the power it needs. This gap that never closes is the steady-state error of a proportional controller. To keep 20 °C the heater needs about 0.6 of its power, so the error is about 0.6 ÷ gain.
- Gain 1 gets much closer, 19.4 °C, with a small overshoot to 20.2 °C on the way, which dies away.
- Gain 3 reacts so strongly that the delays in the loop catch it out: by the time the thermostat feels the warmth, the heater has already given too much, and then it cuts back too far. The room overshoots to 20.6 °C and keeps swinging, between 19.1 and 20.4 °C, like the on/off thermostat. A proportional controller with a very high gain behaves almost like an on/off one.
So no gain is right for everything: a low gain is steady but falls short, and a high gain comes close but overshoots and oscillates. Engineers fix the steady-state error by adding a second part to the controller, which adds up the error over time and keeps pushing while any gap is left (integral control), and calm the overshoot with a third part, which watches how fast the temperature is changing (derivative control). Together these three make the PID controller, found in almost every machine that holds something steady: a factory oven, a car’s cruise control, a drone hovering in the wind.
In a room heater with a thermostat, which part is the actuator?
Pick an answer to see why.
A proportional controller keeps a room at 18.8 °C when the set point is 20 °C. What would make the gap smaller, and what is the risk?
Pick an answer to see why.
Random simulations: Monte Carlo
The ball, the orbit, the SIR model, the leopards and the heated room have one thing in common: run them twice and you get exactly the same answer. They are deterministic models. But much of the world isn’t like that. Whether one sick student meets a friend today is chance. So is whether a bus is full, or whether two people in a class share a birthday. A model with chance in it, run with random numbers, is a stochastic model, and running it many times to see what usually happens is a Monte Carlo simulation. In Grade 9 you estimated π by dropping random dots on a square, and in Grade 10 you ran a ticket counter’s morning a hundred times. Now for the questions they left: how many runs are enough, and what can chance do that a deterministic model can’t?
More trials, a steadier answer
Here is Grade 9’s estimate of π again, but each one made 10 times over, with different random dots each time, for four sizes:
import random def estimate_pi(dots): """Drops dots at random on a square of side 1; 4 × (share inside the quarter circle) ≈ π.""" inside = 0 for i in range(dots): x = random.random() y = random.random() if x * x + y * y < 1: inside += 1 return 4 * inside / dots random.seed(4)for dots in [100, 1000, 10000, 100000]: tries = [estimate_pi(dots) for i in range(10)] print(f"{dots:7} dots: from {min(tries):.3f} to {max(tries):.3f}")Output
100 dots: from 2.720 to 3.400 1000 dots: from 3.072 to 3.228 10000 dots: from 3.122 to 3.165 100000 dots: from 3.135 to 3.148Every estimate is different, but they crowd closer round 3.1416 the more dots each uses. Look at how much closer. The spread from lowest to highest goes 0.68, 0.16, 0.04, 0.01: each time the dots are multiplied by 10, the spread shrinks by about 3, not by 10. That is a general law of random sampling: the typical error of a Monte Carlo estimate shrinks in proportion to 1 ÷ √(number of trials). Ten times more trials give about √10 ≈ 3.2 times less error; to make the error 10 times smaller you need 100 times more trials. Monte Carlo gets close quickly, but getting very close is slow.
So never report a Monte Carlo answer without saying how much it can vary. Run it several times, as here, and give the range (or, as in Grade 10, the spread).
A Monte Carlo estimate with 1,000 trials typically varies by about ±2%. About how many trials would bring that to ±0.2%?
Pick an answer to see why.
A question with a surprising answer
Your class has 40 students. What is the chance that two of them share a birthday? Most people guess it is small: there are 365 days, and only 40 students. Instead of guessing, simulate it. A made-up class is 40 random birthdays, each a number from 1 to 365; then check whether any number appears twice. Make 10,000 such classes and count:
import random def shared_birthday(students): """One made-up class: True if two or more students share a birthday.""" birthdays = [random.randint(1, 365) for i in range(students)] return len(set(birthdays)) < students # a set keeps each day only once random.seed(7)classes = 10000shared = 0for c in range(classes): if shared_birthday(40): shared += 1print("Classes of 40 with a shared birthday:", shared, "of", classes)print(f"Chance: {100 * shared / classes:.1f}%")Output
Classes of 40 with a shared birthday: 8897 of 10000Chance: 89.0%89%: in nine classes of 40 out of ten, two students share a birthday. The surprise is that it isn’t about your birthday matching someone’s: it is about any pair, and 40 students make 780 pairs. Mathematics can work out this chance exactly (it is 89.1%), so here you can check the simulation and see it was close. For most questions with chance in them, there is no exact answer to check against, and Monte Carlo is the only way.
Chance inside a model
Back to the student who came back to the hostel with flu. The SIR model says that with R₀ above 1 an epidemic always takes off. But when there is only one sick person, chance matters a great deal. She might get better before she meets anyone closely; or she might pass it to one friend, who stays in bed. Here is a stochastic model of a hostel of 100 students. Each day, each sick student has a 50% chance of meeting someone closely enough to pass it on (a random student; if they haven’t had it, they catch it), and a 25% chance of getting better, so the illness lasts 4 days on average and R₀ is about 0.5 × 4 = 2:
import random def one_outbreak(students, pass_chance, better_chance): """One student comes back sick. Gives back how many catch it in all, her included.""" sick = [0] # student 0 is the first one sick had_it = {0} while sick: # one day at a time, while anyone is ill still_sick = [] for s in sick: if random.random() < pass_chance: # meets someone closely today other = random.randrange(students) if other not in had_it: had_it.add(other) still_sick.append(other) if random.random() >= better_chance: # not better yet still_sick.append(s) sick = still_sick return len(had_it) random.seed(11)sizes = [one_outbreak(100, 0.5, 0.25) for i in range(1000)]small = len([n for n in sizes if n < 10])print("Fizzled out (fewer than 10 caught it):", small, "of 1000")print("Big outbreaks, average size:", round(sum(n for n in sizes if n >= 10) / (1000 - small)))Output
Fizzled out (fewer than 10 caught it): 357 of 1000Big outbreaks, average size: 77In about a third of the runs the flu fizzles out: fewer than 10 students, often only the first, ever catch it. In the other two thirds, about 77 of the 100 do, close to what the SIR model says for R₀ = 2 (80%). The deterministic model gives only the second answer. The stochastic model shows both, and how likely each is: a hostel warden who sends the first sick student home quickly may stop it altogether, by luck and good sense together.
Why might a stochastic model of the hostel show the flu dying out, when the SIR model with the same R₀ says it always spreads?
Pick an answer to see why.
Making data that fits its parameters
A stochastic model makes simulated data: here, how long each student is sick, and whom each meets. Before trusting the results, check that the simulated data really fits the parameters you meant, as Grade 10 did with marks and arrival times. In the hostel model, the illness should last 4 days on average. Does it? Make the sick days on their own, the way the model does, and measure:
import random random.seed(2)days = []for student in range(10000): sick_for = 1 while random.random() >= 0.25: # not better yet: another day sick_for += 1 days.append(sick_for)print("Average days sick:", round(sum(days) / len(days), 2))print("Longest:", max(days), "days")print("Better after 1 day:", days.count(1), "of 10000")Output
Average days sick: 3.98Longest: 30 daysBetter after 1 day: 2511 of 10000About 4 days on average, as intended, and a quarter better after one day. But look at the longest: 30 days. Real flu doesn’t last a month. A model that gives each day the same 25% chance of getting better makes some illnesses absurdly long. That doesn’t matter much here (very few are that long), but it is the kind of thing checking the simulated data finds, and it is an assumption to list.
Checking a model against data
A model that has never been compared with the real world is only an idea. The last step of the loop in Figure 5.1, and the most important, is to compare what the model says with what really happened, and to ask what the differences mean.
A model of Nepal’s population
Nepal has counted its people in a census about every ten years since 1911. Here are the counts, in millions:
| Census | 1911 | 1920 | 1930 | 1941 | 1952/54 | 1961 | 1971 | 1981 | 1991 | 2001 | 2011 | 2021 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| People (millions) | 5.64 | 5.57 | 5.53 | 6.28 | 8.26 | 9.41 | 11.56 | 15.02 | 18.49 | 23.15 | 26.49 | 29.16 |
The simplest model of a population says it grows by the same share every year: next year = this year × (1 + rate), the same rule as money in a bank. Its one parameter, the rate, can be fitted to data: chosen so that the model matches two censuses exactly. Suppose that in 2001 a planner fitted it to the three decades before, 1971 to 2001, and used it to plan schools and hospitals for 2011 and 2021:
census = {1911: 5.64, 1920: 5.57, 1930: 5.53, 1941: 6.28, 1954: 8.26, 1961: 9.41, 1971: 11.56, 1981: 15.02, 1991: 18.49, 2001: 23.15, 2011: 26.49, 2021: 29.16} def grow(first, last, to_year): """Fits a steady growth rate between two censuses, and carries it on to to_year.""" years = last - first rate = (census[last] / census[first]) ** (1 / years) - 1 return rate, census[last] * (1 + rate) ** (to_year - last) rate, guess = grow(1971, 2001, 2001)print(f"Fitted on 1971 to 2001: {100 * rate:.2f}% a year")for year in [2011, 2021]: rate, guess = grow(1971, 2001, year) off = 100 * (guess - census[year]) / census[year] print(f"{year}: model {guess:.2f} million, census {census[year]:.2f} million, model {off:+.0f}%")Output
Fitted on 1971 to 2001: 2.34% a year2011: model 29.18 million, census 26.49 million, model +10%2021: model 36.78 million, census 29.16 million, model +26%(** (1 / years) is the years-th root: the rate that, multiplied in years times, turns the first count into the last. {off:+.0f} prints the sign, + or −.)
The model matched the past perfectly, because it was fitted to it, and then missed the future badly: by 2021 it expected 7.6 million more people than were counted. A school planned for 37 million would have stood half empty. That is the most important lesson of this section: a model that fits the data it was built from has passed no test at all. The test is data it hasn’t seen.
What the differences show
When a model and the data disagree, the disagreement is information. It says one of the model’s assumptions is wrong, and it is worth finding out which. The steady-growth model assumes that each year the same share of people are born, die, arrive and leave. Between 2001 and 2021, in Nepal, all of that changed:
- Fewer children. Nepal’s women had on average more than 6 children each in the 1970s, and 2.1 by 2022 (the Nepal Demographic and Health Survey). Fewer births mean slower growth.
- People abroad. The census counts the people living in Nepal. In 2021 it also counted 2,190,592 Nepalis who were absent abroad, working or studying, almost three times as many as in 2001 (762,181). They aren’t in the 29.16 million.
A better model would follow births, deaths and people leaving and coming back separately, each with its own rate, fitted to its own data. That is how the real population projections are made: they are models with many parts, each checked.
To evaluate a model or a simulation, yours or someone else’s, ask:
- What question does it answer? And is it the question you need answered? The SIR model answers “what shape does an epidemic take, and why does it stop?”; it doesn’t answer “how many beds will Bhaktapur hospital need next March?”
- What does it assume? List the assumptions. Which could be wrong, and would that make the answer bigger or smaller?
- Was it tested on data it didn’t see? Fit a model on part of the data, and test it on the rest (for a model of time, on the later years). A model only fitted is untested.
- How sure is it? A deterministic model gives one number; the truth is a range. Change each uncertain parameter a little and see how much the answer moves; for a stochastic model, run it many times and give the spread.
- How far ahead can it see? The further from its data a model reaches, the less it can be trusted. The population model was off by 10% after 10 years and 26% after 20.
A model was fitted to Nepal’s censuses of 1971 to 2001 and matches them exactly. What does that show about how good it is?
Pick an answer to see why.
A model’s forecast and the real data begin to differ more and more after a few years. What is the best first step?
Pick an answer to see why.
Project: model a real system
# Part C: the SIR model for your district, with a chartimport matplotlib.pyplot as plt people = 432132 # change to your district's populationinfected, recovered = 10, 0susceptible = people - infectedr0, days_sick = 2, 7spread = r0 / days_sick s_list, i_list, r_list = [], [], []for day in range(250): new_cases = spread * susceptible * infected / people new_recoveries = infected / days_sick susceptible = susceptible - new_cases infected = infected + new_cases - new_recoveries recovered = recovered + new_recoveries s_list.append(susceptible) i_list.append(infected) r_list.append(recovered) plt.plot(s_list, label="susceptible")plt.plot(i_list, label="infected")plt.plot(r_list, label="recovered")plt.xlabel("Day")plt.ylabel("People")plt.title(f"The SIR model, R0 = {r0}, {people:,} people")plt.legend()plt.show()In short
Exercise
What is abstraction in building a model?
Pick an answer to see why.
In a time-step simulation, what is the state?
Pick an answer to see why.
A simulation uses Euler’s method with a time step of 0.2 s, and its answer is off by 6 m. The step is changed to 0.02 s. About how far off will the answer be?
Pick an answer to see why.
For measles, R₀ is about 15. About what share of people must be immune to stop it spreading?
Pick an answer to see why.
A Monte Carlo simulation is run with 400 trials, and then with 40,000. How does the typical error change?
Pick an answer to see why.
Which of these is a stochastic model?
Pick an answer to see why.
What is the difference between a model and a simulation? Give an example of each from this unit.
Answer
A model of how long a bus takes from Kathmandu to Pokhara uses the distance, the bus’s usual speed on each stretch, and the stops for meals. List three things it leaves out, and three assumptions it makes. Which assumption is most likely to make it wrong in the monsoon?
Answer
Explain, with the update rule of the thrown ball, why a smaller time step gives a more accurate answer, and why it isn’t free.
Answer
In Unit 1 you modeled things as objects. Write a class Ball with attributes x, y, vx and vy, and a method step(dt) that moves it one time step with Euler’s method (no air). Use it to find how long a ball thrown straight up at 10 m/s stays in the air, with a step of 0.001 s.
Answer
A friend writes an orbit simulation with Euler’s method and finds the planet slowly spiraling away from the Sun. She says, “The computer’s arithmetic must be wrong.” Is she right? Explain, and say how to fix it.
Answer
In the SIR model, explain in your own words what happens on the way to the peak, at the peak, and after it. Why is the peak the moment the number of new cases a day equals the number of recoveries a day?
Answer
Using the herd immunity rule, find the share that must be immune for diseases with R₀ = 1.5, 3 and 6. Why can a disease with R₀ below 1 never cause an epidemic?
Answer
In the predator–prey model, the prey peak and then the predators peak a little later. Explain why, step by step, using the model’s four rules.
Answer
Write a Monte Carlo program to estimate the chance that, when you roll two dice, they add up to 7. Use 100,000 rolls. What is the exact answer, and how close is yours?
Answer
Explain why a Monte Carlo answer should always be given with how much it can vary. How would you find that out?
Answer
In 2001 a planner fits a steady-growth model to Nepal’s censuses of 1971 and 2001, and predicts 36.8 million people for 2021. The census of 2021 counts 29.16 million. Give two reasons for the difference, and say what each shows about the model’s assumptions. How should the planner have tested the model before using it?
Answer
A news report says: “A computer model predicts that dengue cases in Kathmandu will double every week until the end of the year.” Using what you learned in this unit, write four questions you would ask before believing it.
Answer
A house has a 1,000-liter tank on its roof, filled by a pump that gives 20 liters a minute. An automatic controller starts the pump when the water falls below 250 liters and stops it when it reaches 950 liters. (i) Name the sensor, the controller, the actuator and the set point. (ii) The house uses 8 liters a minute from 6 to 8 in the morning and 6 to 8 in the evening, 2 liters a minute at other times from 8 a.m. to 10 p.m., and none at night. Write a simulation of one day, a minute at a time, starting with 600 liters at midnight, that counts how many times the pump starts. (iii) Someone suggests starting the pump below 940 liters instead, “to keep the tank always full”. Change your program to find out what happens, and explain why the controller has a wide dead band.
Answer
Quiz yourself: Data and analysis, Grades 6–12 →
Practice every question in the book, and keep track of the ones you miss →